

Buying Chips Isn't the Same as Running a Data Center
Nvidia, AMD, and Google's latest moves show that chips, power, and data centers all have to scale together.
AI & TechBuying Chips Isn’t the Same as Running a Data Center
In a BG2 interview on October 31, 2025, Microsoft CEO Satya Nadella said the company lacks the power and data center capacity to install the chips it has already secured. In other words, buying more chips doesn’t mean you can put them to work right away. Interview coverage
That comment came back to mind when I saw a string of announcements in February 2026. Meta announced a long-term partnership with Nvidia on the 17th and with AMD on the 24th. Google unveiled a new data center in Texas along with its power procurement plans, also on the 24th. I think these announcements need to be read together. Which chips a company uses isn’t the only thing that determines the scale of its AI business—where it installs them and what powers them matter just as much.
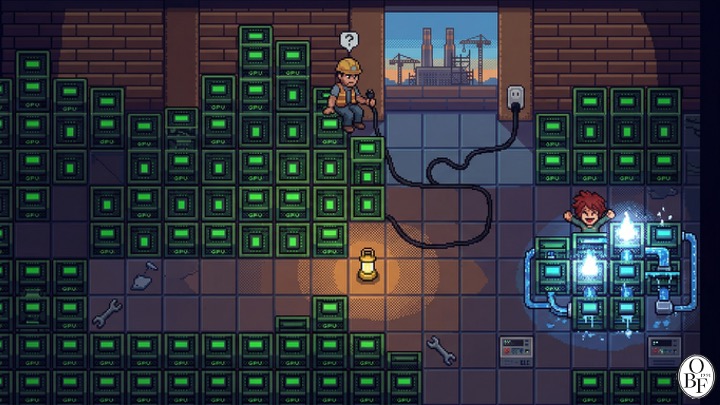
AI infrastructure fundamentally needs three things: chips to handle computation, data centers with the power and cooling to run them, and memory to move and store the data that computation requires. If any one of these is missing, securing the other two won’t let you scale your service as planned.
Meta Is Expanding Its Chip Supplier Base
Meta announced that, through its partnership with Nvidia, it will roll out millions of Blackwell and Rubin GPUs over multiple years. It then announced a deal with AMD to build out up to 6GW of GPU infrastructure in phases. The first shipments are scheduled for the second half of 2026. That 6GW figure refers to capacity to be built going forward — it is not infrastructure already running, nor a separate power allocation already secured. Nvidia announcement, Meta announcement
Meta is also developing its own AI chip, MTIA. I read this as a strategy of expanding options so that the business as a whole isn’t hostage to any single supplier’s delivery timelines or pricing.
There’s more than one way to choose your chips, too. You can buy GPUs directly from Nvidia or AMD, or you can use a cloud provider offering Google’s TPUs or Amazon’s Trainium. It’s worth distinguishing between contracts to purchase chips outright and contracts to use cloud compute.
In October 2025, Anthropic announced plans to scale its use of Google Cloud TPUs up to 1 million chips. At the time, it also noted it was using Nvidia GPUs and Amazon Trainium alongside them. It’s a case of a cloud provider that built its own chip also supplying large-scale compute to outside customers. Anthropic announcement
I don’t read these moves as meaning Nvidia’s competitive edge is disappearing. There’s real cost involved in adapting software and development tools you already use to a different chip. Companies have to factor in not just chip prices, but how efficiently they can run their own models and the work required to make the switch.
Securing Power Takes Its Own Timeline
Of the three conditions, the one I weigh most heavily is power. That’s because chip orders and the construction of power generation and transmission facilities don’t move at the same pace.
On February 24, Google announced a data center under construction in Wilbarger County, Texas. The announcement included plans to work with AES to secure nearby clean energy supply and to reduce water use through advanced air-cooling systems. Google stated that, across Texas as a whole, it has now contracted for more than 7,800MW of new generation and power capacity. That figure isn’t the power consumption of Wilbarger County alone, nor does it mean all the contracted facilities are already operational. Google announcement
In its 2025 report, the International Energy Agency projected in its base-case scenario that global data center electricity consumption would grow to roughly 945TWh by 2030 — more than double the 2024 figure. The report also noted that building out power infrastructure can take longer than building the data centers themselves. IEA report
That’s why, when I look at investment announcements, I check both the power contracts and the actual supply timeline together. Even if a data center building is completed, if it can’t secure the electricity it needs, it won’t be able to run chips at the scale planned. What stood out to me in Google’s announcement was that, alongside securing chips, it’s also preparing its power procurement.
Memory expansion is part of AI infrastructure, too
The condition that ties Korean companies directly into this picture is memory. HBM stacks multiple layers of DRAM to deliver data to AI accelerators at high speed. A server’s ordinary DRAM holds data currently being worked on, while NAND-based SSDs store data. All are necessary, but they don’t play the same role.
In its Q3 2025 earnings call in October 2025, SK Hynix said it had finished discussing 2026 HBM supply with major customers and had also locked in customer demand for its 2026 DRAM and NAND production. The company explained that demand is strong from customers looking to secure volume ahead of time, in line with its own production plans. SK Hynix earnings announcement
When a memory maker increases HBM output, that doesn’t mean ordinary memory supply grows at the same rate. Micron has explained that, for the same process node and the same storage capacity, HBM3E requires roughly three times as many wafers as DDR5. When manufacturing capacity is fixed, shifting more of it toward HBM can shrink the capacity left over for ordinary DRAM. Micron earnings materials
Micron’s December 2025 announcement that it would exit its Crucial consumer business is another sign of this shift in priorities. What’s being wound down is the Crucial-branded retail business sold directly to consumers; Micron said it would continue selling enterprise products under the Micron brand. Micron announcement
As service usage grows, the memory needed for inference is becoming more important too. For instance, when a language model generates a response, it stores some of its previously computed values in a KV cache for reuse. In the basic architecture, this cache grows in proportion to the length of the context being processed. The longer the documents being read, or the more user requests being handled simultaneously, the more memory usage needs to be managed. Nvidia researchers’ explanation of the KV cache
Oswarld’s Lens
Watching this competition unfold, I was reminded of situations I often saw while working as a GTM strategist. Solve one problem in a product, and another, previously less visible problem ends up blocking further expansion. AI infrastructure works the same way: adding more chip supply alone doesn’t finish the job. Power and memory both have to be ready before the chips you’ve secured can actually be put to use.
From this angle, I think Google is relatively well-positioned. It’s developing its own TPUs, lining up external customers to use them, and simultaneously securing power supply in Texas. Of course, memory still has to be sourced externally, and we need to watch whether power contracts actually translate into operational timelines. Even so, I rate highly the fact that Google is lining up multiple conditions at once.
Meta’s supplier diversification also strikes me as a sensible choice. Running Nvidia, AMD, and its own MTIA chips together reduces the risk of being locked into a single supplier. But having more chip options is a separate matter from solving power and memory shortages. When and where contracted equipment can actually be brought online still matters just as much.
For Microsoft, what concerns me is the facility shortage Nadella himself mentioned. If the period during which secured equipment sits idle stretches on, the company will be constrained in scaling up service even where demand exists. I plan to watch the pace at which usable capacity actually comes online just as closely as the investment figures themselves.
For SK hynix and Samsung Electronics, expanding memory demand is an opportunity. According to Counterpoint data cited by SK hynix, the company held a 62% share of HBM shipments in Q2 2025. That figure underscores how large a role Korean companies play. Still, a shipment share in one particular quarter doesn’t guarantee the same share in next-generation products. SK hynix market outlook report
The memory market has always seen supply swings. Even if capacity is expanded based on current demand, how much demand will have grown by the time new plants come online is a separate question. I think what happens to supply and demand after expansion matters just as much as the current shortage does.
Improving the efficiency of AI services can reduce the chips, power, and memory required. But that doesn’t immediately resolve the parts that require actual physical facilities. In the end, evaluating infrastructure investment requires looking together at the number of units purchased, the timing of power supply, and memory procurement plans. And beyond that, we need to check whether the AI services delivered through that infrastructure generate enough revenue to recoup the investment.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


Related issues
Why Rare Earths, Nuclear Treaties, and Power Grids Connect
New START's expiry, rare-earth supply chains, and shifts in power and EV industries reveal the real terms of great-power competition.
AI & TechIf Brainwaves Train Robots, What Do Experts Deserve?
I look at how EEG-based robot training actually works, and why expert consent and compensation must be settled before deployment.
AI & TechAmazon's 1 Million Robots: What Actually Changes at Work
Robot counts and hourly costs alone don't explain the shift in hiring—Amazon's automation and Digit's warehouse rollout show why.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?