

Qwen's Chief Departs as Alibaba Restructures Its AI Unit
Alibaba's Qwen tech lead resigned days before the company launched a new AI business group, Token Hub.
AI & TechQwen’s Chief Steps Down as Alibaba Restructures Its AI Organization
In early March 2026, Lin Junyang (林俊旸), the technical lead of Alibaba’s Qwen1, posted a farewell message on social media.
“me stepping down. bye my beloved qwen.”
He was the key figure behind building Qwen and engaging with the global developer community, and colleagues expressed regret at the news of his departure. Then, on March 16, Alibaba announced the formation of a new business group called Alibaba Token Hub (ATH), to be led directly by CEO Eddie Wu.
The two events happened close together in time, but it hasn’t been fully disclosed why he resigned or whether it’s connected to the reorganization. What we can confirm is that Alibaba is trying to coordinate its AI research and services under a single business group. Let’s look at which organizations were brought together, and how Alibaba intends to generate revenue through this move.
From Model Research to Business-Ready Products
ATH encompasses the Tongyi Lab, the MaaS business, the Qwen business unit, the Wukong business unit, and the AI Innovation business unit. It’s a structure that ties together everything from research to the products customers actually use.
- Tongyi Lab: Researches and develops foundation models2 like Qwen.
- MaaS (Model-as-a-Service): Handles the service through which developers and enterprises use models in the cloud.
- Qwen business unit: Handles consumer-facing products, such as AI apps that end users interact with directly.
- Wukong business unit: Develops an AI platform that handles enterprise workflows.
- AI Innovation business unit: Covers new AI products and use cases.
Wukong isn’t an image-generation brand — it’s an enterprise AI work platform. According to Alibaba’s March 17 announcement, it’s designed to handle tasks like document editing, spreadsheet work, and meeting transcription, and at the time it was in a massive-scale beta test. Alibaba said it would be available both as a standalone app and inside DingTalk.
Alibaba described ATH’s role in three stages:
Create tokens, deliver them, and put them to use.
You can read this as an intent to connect the research that improves model capabilities, the technology and business that deliver models as a service, and the apps and work tools that actually use that service.
Looking at this fragment, I compared it against the Korean source carefully.
How Token Usage Connects to Revenue
Tokens3 are the units a language model uses to process input and output. Many model APIs charge based on the number of input and output tokens. That said, tokenization methods and pricing differ from model to model, and there are other billing schemes too, like app subscriptions or enterprise contracts.
In the name “Token Hub,” I read an intent to link model development more closely to customer usage and revenue. There’s no need to read this as a declaration that they’re giving up on research — a good model is still what gives customers a reason to choose a given API or product in the first place.
There’s a pricing-competition problem lurking here. Lowering API unit prices can make it easier to attract customers, but even if usage rises, revenue and profit may not rise enough to match. And comparing prices across a single line item, when model size, quality, and input/output conditions all differ, makes it hard to tell how cheap something actually is.
Beyond API fees, Alibaba has other channels: selling cloud resources and enterprise products. Chairman Joe Tsai said, in an explanation the company released in February 2026, that even after open-sourcing Qwen, Alibaba can still earn cloud revenue if customers train and run the model on its own infrastructure. It’s an account of how an open model and paid services can operate side by side.
ATH can be seen as an organization built to coordinate these interconnected businesses — building the model, offering it via API, and getting people to use it through products like the Qwen app and Wukong. Wukong integrates with DingTalk, and Alibaba has said it plans to gradually connect other services too, like e-commerce and cloud. It’s worth distinguishing between connections that are planned and features that are already working.
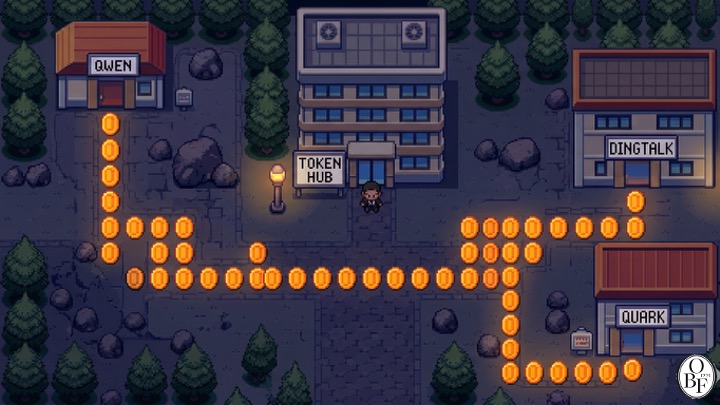
An illustration depicting Alibaba’s connected AI services. Here, “tokens” refers to the model’s processing units, not cryptocurrency.
Can a widely used model actually grow paying customers?
The fact that Qwen is widely used and the fact that Alibaba profits from that use are two separate things that need to be checked independently.
AI companies run their businesses through some combination of free apps, individual subscriptions, API billing, enterprise contracts, and cloud sales. Willingness to pay and competitive conditions differ by country, but it’s hard to reduce this to a single framework of “the West charges directly, China profits indirectly.” Even within the same company, revenue structures differ from service to service.
In Alibaba’s case, developers can download Qwen and run it on their own servers or on another company’s cloud. This increases Qwen’s usage, but the cost of running it doesn’t necessarily translate into revenue for Alibaba. Conversely, if someone chooses Alibaba’s managed API or cloud, they become a paying customer.
Alibaba announced in February 2026 that cumulative downloads of Qwen models had surpassed 1 billion, with more than 200,000 derivative models. This means many models are being adapted for other purposes through fine-tuning4 and similar methods. But downloads can include repeat downloads, and a single derivative model doesn’t equal a single user or a single paid contract.
So to assess a model’s influence, you need to look at downloads and derivative models; to assess business performance, you need to look separately at paying customers, usage, revenue, and cost. The founding of ATH can be understood as an attempt to connect these two things — but a reorganization alone doesn’t mean that connection has actually been completed.
How Should We View the Departure of Those in Charge
Personnel changes on the Qwen team have also drawn attention.
Early-March reports mentioned not only Lin Junyang, but also the departures of Hui Binyuan, who led Qwen Code, and Wei Bowen, who headed post-training5. Recode China AI reported that Hui Binyuan had moved to Meta in January. Still, it’s hard to lump together everyone’s departure timing and reasons as if they were a single event.
Recode China AI and others reported that a reorganization splitting Qwen’s unified development organization into functional teams—pre-training, post-training, multimodal6, and so on—along with the resulting shifts in scope of responsibility, may have been a source of friction. This explanation comes from news reports, and should be kept separate from any definitive reason for departure that Lin Junyang has stated himself.
How to divide up a research organization is, in practice, a genuine management question. When a single team owns the entire model-development process, decision-making can move faster; when the work is split by function, it may be easier to share specialized talent and resources. Which approach makes sense depends on the nature of the work and the size of the organization. It’s not fair to assume, as a simple binary, that researchers only want openness while management only wants revenue.
Eddie Wu’s announcement that he would personally lead the business group signals an intent to strengthen coordination across the organization. Whether this is a direct response to the personnel departures, or whether it resolves any existing friction, is hard to judge from publicly available information alone.
Oswarld’s Lens
I read ATH as a management move to bring model research, service delivery, and customer acquisition under a single line of accountability.
From a GTM standpoint, what matters is pinpointing exactly where the handoff breaks down between building a product and getting customers to actually use it. Even a great model is hard for enterprise customers to adopt if the API is unstable; even a great API sees slow adoption if applying it to real workflows is too complicated. I think the whole point of stitching different teams together under ATH is to fix these connective-tissue problems.
What I’ll be watching alongside this is the policy on open-weight models. Downloadable model files and paid APIs can coexist perfectly well — so a sharper focus on monetization doesn’t automatically mean Qwen’s open releases are about to stop. Still, which models get released under which license, and how updates and support continue afterward, are conditions developers care about a great deal.
Anyone who has built a product on top of Qwen can’t help but care about whether future models will be released openly and stay compatible. They’ll want to see whether releases, documentation, and license terms keep coming steadily even after a key executive departs. To me, that kind of follow-through in practice is the real basis for judging developer trust.
On the business side, there are three things I want to see. Are paying customers and usage growing? How does that growth compare to the cost of delivering the service? And do developers keep choosing Qwen? Only if these metrics improve can we say the ATH reorganization actually translated into results.
Closing
The structure of ATH shows that Alibaba wants to manage its model research and AI service revenue more tightly under one roof. Products like Wukong, which get applied to enterprise workflows, were folded into it as well.
Meanwhile, the reasons behind the departures of Qwen’s leadership haven’t been fully disclosed. It’s worth separating the reporting on internal organizational friction from the business plans that have actually been confirmed, and watching how product direction and developer support evolve from here.
This is also a good moment to check whether the features our own organizations build are actually translating into real usage. That means getting concrete about where customers drop off, what kind of support they need to adopt a product, and whether the cost and quality justify continued use. Personally, I’m less curious about what a business unit gets named than about who’s actually responsible for solving these problems.
Looking at this fragment, I compared it against the Korean source for structural fidelity, glossary compliance, and completeness. The translation is accurate and complete—all links, footnotes, numbers, and the image marker match. No Hangul remains, and “Oswarld” is correctly used (not “Oswald”). No corrections are needed.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
- Reuters, Alibaba CEO takes helm of new AI-focused business group, 2026.3.16.: the CEO’s role and the organizations folded into ATH.
- Alibaba, Wukong enterprise AI platform announcement, 2026.3.17.: product features, DingTalk integration, beta testing, and future connectivity plans.
- Alibaba, Joe Tsai on the Future of Open-Source AI, 2026.2.6.: the company’s stated position on the relationship between open models and cloud revenue, and figures on Qwen downloads and derivative models.
- Alibaba, AI and cloud business update, 2026.3.19.: earnings materials explaining the roles of ATH and MaaS.
- Alibaba, Agentic AI business direction, 2026.3.23.: the three stages of token generation, provision, and utilization, and enterprise product strategy.
- TechCrunch, Report on Qwen technical lead’s departure, 2026.3.3.
- Recode China AI, Alibaba Qwen’s Lead Just Stepped Down, 2026.3.4.: reporting and analysis on the personnel change and the organizational reshuffle behind it. Read this separately from confirmed facts about the reason for the departure.
Footnotes
-
Qwen (通義千問): the name of Alibaba’s AI model family. Note that the consumer-facing app of the same name and the underlying model itself are distinct things. ↩
-
Foundation Model: an AI model trained on large-scale data so it can be applied to many different tasks. ↩
-
Token: the unit of text (and other data) that a model processes. The relationship between character count and token count varies by language and by how a given model tokenizes text. Many APIs also price input and output tokens differently. ↩
-
Fine-tuning: the process of further training an already-trained model on additional data so it’s adapted to a specific task or format. ↩
-
Post-training: additional training conducted after pretraining to improve response style, reasoning ability, and similar qualities. ↩
-
Modality: the type of data a model processes, such as text, images, or speech. A model that handles multiple types together is called multimodal. ↩
Related issues
Gemma 4, GLM-5, and the Real Cost of Running Agents
Google's Gemma 4 and a fresh GLM-5 benchmark reopen the question of what an agent model should actually cost to run.
AI & TechAnthropic's $14B ARR vs. $5B Cumulative Revenue
Run-rate and cumulative revenue mean different things—AI growth figures need cost and retention context too.
AI & TechWhat 81,000 People Want From AI
Nearly 80,000 Claude users shared what they want from AI—and the same answers revealed both hope and worry.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?