Sam Altman Thinks Your PC RAM Is Wasted
Surging memory prices are already reallocating silicon from consumer rigs to AI data centers.
AI & TechWhere Did the ‘Gaming PC’ Come From?
Over the past few days, a single screenshot circulated across Korean online forums and social media. It claimed that OpenAI CEO Sam Altman called putting RAM into gaming PCs “terrible.” Traced to its source, the quote came from an article by the US gaming outlet IGN, headlined: “Altman Thinks It’s Terrible That Your Gaming PC Has RAM.”
IGN’s source was an episode of Stripe’s podcast, Cheeky Pint, released on October 29. Altman sat down with Stripe co-founder John Collison for a wide-ranging conversation spanning PHP security vulnerabilities, agent teams, and Navier-Stokes proofs. The controversial remark lands around the 29-minute mark. And in that exchange, Altman never once mentioned gaming.
What he was actually discussing was local inference1. He began by noting that as open-weight models proliferate, many people want to run them directly on their own machines. Then he pushed back. If globally scarce DRAM ends up sitting inside household computers being used just 5% of the time, that allocation is, from a global perspective, “quite terrible.” His point was simple: when supply is this tight, pooling memory in the cloud to run continuously makes far more sense.
As the exchange migrated from the raw conversation to a gaming outlet’s headline, from that headline to forum threads, and from forum threads to social media screenshots, context was stripped away at every turn. All that remained in the final screenshot were two phrases: “gaming PC” and “terrible.” Yet the first never appeared in the original transcript.
Two days later, on October 31, Altman met with around 50 CEOs and senior executives from Samsung affiliates at the Samsung Leadership Development Center in Yongin, Gyeonggi Province. The session was titled “The Next 10 Years Transformed by AI: Choices for Enterprises,” and Altman was joined by Richard Ho, OpenAI’s Vice President of Hardware, who oversees custom chip development.
Follow the original conversation, and the starting point looks entirely different from the headlines. Altman’s real opening point was a grievance over why memory supply hasn’t expanded despite such soaring prices, and 5% was merely the figure punctuating that complaint. Today, let’s trace the story in that exact order.
Frustration That the Invisible Hand Isn’t Working
Collison posed the question. There is an adage in the industry: “The cure for high prices is high prices.” When prices climb, someone builds a fab to boost supply, bringing prices back down. So, is that cure on its way? Altman’s answer was a single word: “Bad.” Right now, he argued, the invisible hand is failing.
The reason he cited was the memory industry’s scar tissue. In Altman’s phrasing, DRAM was long a business where you poured in $20 billion in capex to make $19 billion. Having lived through boom-and-bust cycles where overbuilding pushed companies to the brink of bankruptcy, they cannot help but remain cautious about expanding capacity—even as they rake in cash hand over fist. And that is despite each company being poised to generate roughly $100 billion a year in free cash flow2. (That $100 billion figure is Altman’s estimate.)
It may sound like hyperbole, but placing the numbers from Korean chipmakers side by side shows that both pictures are grounded in reality.
| Q1 2023 | Q3 2026 | |
|---|---|---|
| SK Hynix Operating Profit | ₩3.4023 trillion (~$2.5 billion) loss | ₩83.3338 trillion (80% operating margin) |
| Samsung Electronics DS Division Operating Profit | ₩4.5819 trillion loss | ₩106.5 trillion (72% operating margin) |
Just 3.5 years ago, the semiconductor divisions of both companies lost nearly ₩8 trillion combined in a single quarter. Today, they pull in close to ₩190 trillion a quarter.
The language SK Hynix chose in its earnings announcement last week aligns almost perfectly with Altman’s description. Even while projecting that the memory supply shortage will persist through 2030, the company stated that while it would secure additional infrastructure in advance, it would strictly pace the deployment of core resources that actually increase supply—such as equipment move-ins and mass-production ramp-ups—to match demand. On the same day, it announced roughly ₩100 trillion in shareholder returns for fiscal year 2026. The company also cited the sheer difficulty of leading-edge nodes and the time required to build a new fab as reasons for the shortage. Caution is not the only factor; physical reality takes time.
None of this means there is zero expansion. Samsung Electronics announced it would spend ₩76.8 trillion of this year’s ₩84.4 trillion capex on semiconductors, and SK Hynix noted that capex next year would increase significantly over this year, driven in part by bringing its 1st fab in Yongin online. The accurate description is that they are expanding, but not nearly at the pace of the price surge. Why memory makers are this cautious was covered in detail through the lens of NAND flash in Issue 183, “The 4-Year Memorandum SanDisk Secured.”
Doing the Math on That 5% Figure
Let’s return to that 5% figure. First, a caveat: this number is Altman’s own estimate. The conversation didn’t cite a source or a methodology.
Even so, the underlying logic is straightforward. A stick of memory simply works harder in a server juggling requests from multiple users around the clock than in a laptop that sits powered down or idle for most of the day. What’s more, a data center keeps a single copy of model weights in memory and shares it across countless users. Run the model at home, and every user has to load their own duplicate set of weights into memory.
There is, however, a number cutting in the opposite direction. Most memory attached to data-center AI chips is HBM3. At Hot Chips 2026 on August 23, Micron explained that HBM3E consumes roughly 3 times as much wafer area as DDR5 for the same capacity. It added that this gap widens with each successive generation. From a fab’s perspective, moving 1 gigabyte of memory to the cloud consumes as much wafer area as 3 gigabytes of PC memory.
Put the two figures side by side for some simple arithmetic. If PC memory runs at just 5% utilization, it takes 20 gigabytes’ worth of wafer area to yield 1 gigabyte of active work. Because HBM requires 3 times the wafer area for equivalent capacity, as long as cloud memory operates at anything over 15% utilization, the cloud comes out ahead on a wafer basis. And that doesn’t even factor in the efficiency of sharing model weights. If you accept Altman’s 5% figure at face value, the raw memory math leans in his favor. This calculation was done in our editorial process, simplifying the fact that not all server memory is HBM, nor is all laptop memory DDR5.
Other factors fall outside this arithmetic. DRAM in a PC isn’t installed solely for AI; it was already there to run browsers and productivity apps. The real question is the extra capacity purchased specifically for local AI—configurations stepping up to 64 gigabytes or more. Workloads where data cannot leave the building, or tasks that must run offline, operate on an entirely different rubric than simple utilization rates.
You also have to consider who is saying this. OpenAI is in the business of selling cloud inference, and in forging Stargate partnerships with Samsung and SK, it projected needing 900,000 DRAM wafers per month. There have also been reports that Samsung Electronics will supply 6th-generation HBM for OpenAI’s in-house chips. Having skin in the game doesn’t make an argument wrong. But it is worth keeping in mind that the person who benefits most from the claim that DRAM belongs in the cloud is the very person making it.
The Hand Is Already Doing Half Its Job
Altman argued that the invisible hand is failing, but looking at the numbers reveals that the hand’s work splits in 2. Expanding factory capacity is slow. But deciding where to route the DRAM that has already been manufactured? It is doing that at blistering speed.
Proof lies right in Samsung Electronics’ earnings report. In the 3rd quarter, the Device Solutions (DS) division, which oversees semiconductors, posted an operating profit of ₩106.5 trillion (~$76.6 billion), while the Device eXperience (DX) division, responsible for smartphones, TVs, and home appliances, recorded an operating loss of ₩800 billion. That marks 2 consecutive quarters in the red. Domestic press coverage cited rising component costs, particularly for memory, as the main culprit behind deteriorating margins on finished goods, and Samsung Electronics CFO Park Soon-cheol warned that DX division profitability will face continued pressure next year due to cost increases. Inside the very same company, the side selling memory and the side buying it saw diametrically opposed outcomes.
The trajectory of pricing is just as unmistakable. Tom’s Hardware reported that HBM commands roughly 5 times the price of DDR5 per bit. As memory manufacturers dedicate more silicon wafers to HBM and enterprise server products, the volume left for PCs and smartphones shrinks, and prices climb. The allocation Altman envisions—pooling DRAM in cloud infrastructure to maximize shared utilization—is already unfolding through market pricing without anyone planning it. The bill is simply being paid right now by anyone purchasing a laptop or smartphone, and by the companies that build them.
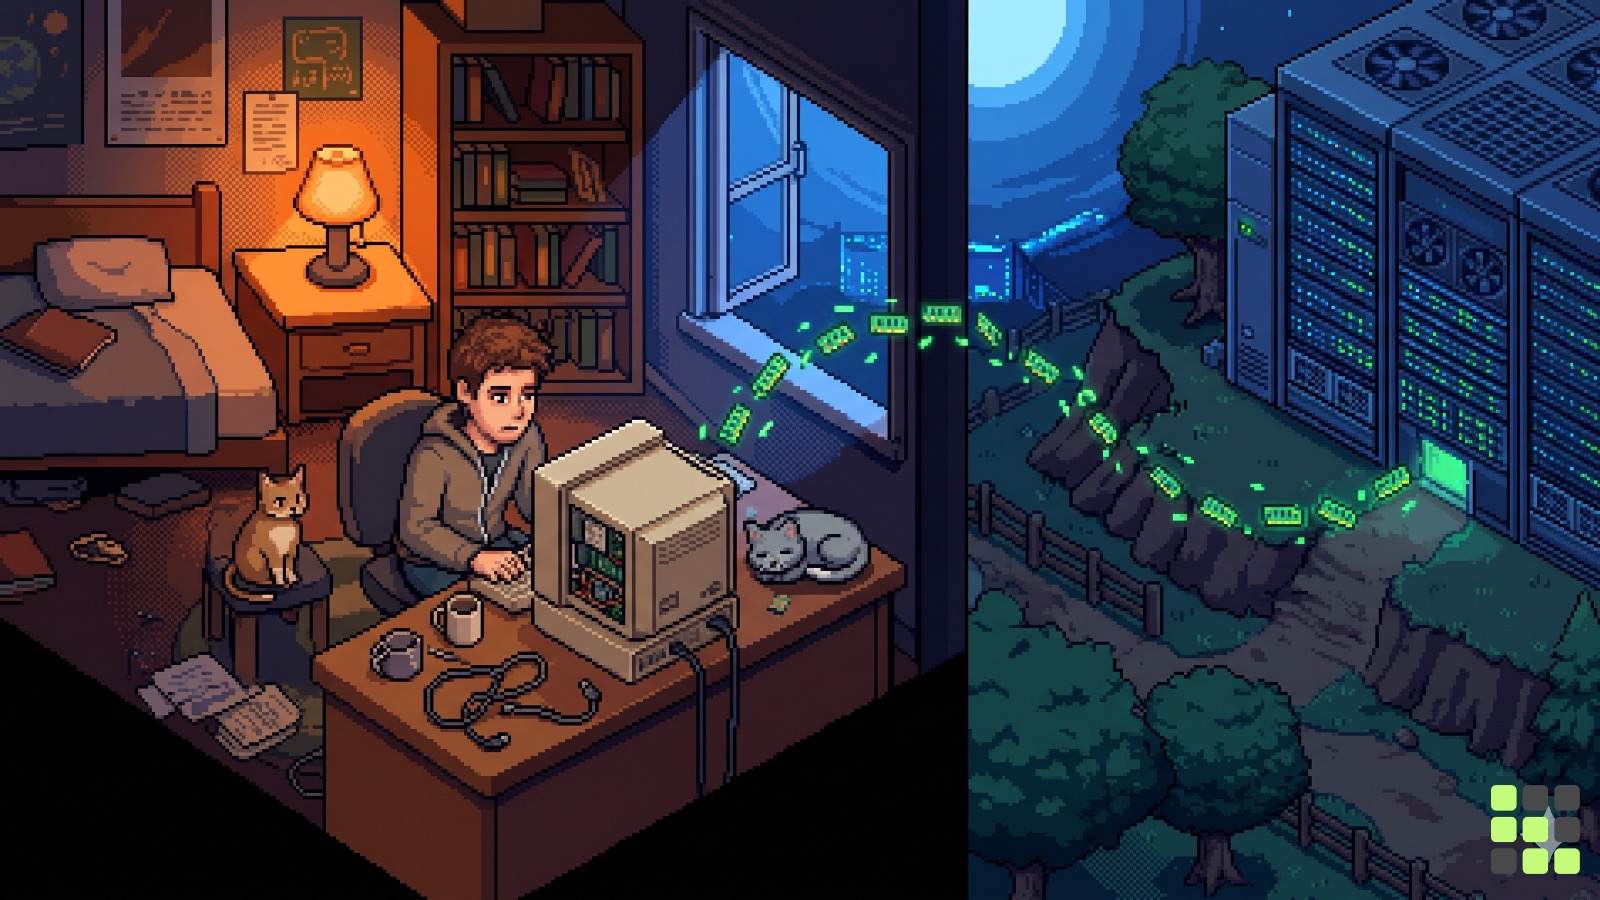
So Altman’s grievance, strictly speaking, concerns only half of the hand’s duties. Allocation has already tipped decisively toward data centers; what is jammed is aggregate supply. As long as total capacity fails to grow, a price war dictates whose desk the remaining DRAM lands on—and right now, the data centers are winning.
Oswarld’s Lens
I think Altman would have been better off keeping quiet. Proposing to pool the world’s DRAM so everyone can share it sounds like a tidy utilitarian calculation, and it makes for an easy out-of-context headline. OpenAI also has every incentive to say this, given that widespread local inference directly hurts its bottom line.
Even so, it is hard to stomach attacks that drag in gaming PCs never mentioned in the original remarks. While everyone takes swings at that straw man, the questions that actually matter vanish: whether that 5% figure holds up, and who benefits from that math. Criticizing his remarks as thoughtless carries weight only when grounded in what he actually said.
I have a foot in both camps here. At home, I run a Mac Studio as an always-on inference server, connecting to it from my MacBook and iPhone. My agents also run on top of it as continuous services. On the flip side, I offload long, token-heavy workloads to Ollama Cloud. Even burning through trillions of tokens, it is vastly cheaper than frontier model APIs.
That is why I believe the right question is not local versus cloud, but how many hours a day that memory actually works. A home server shared across 3 devices works far longer than a solitary laptop, while reserved but idle datacenter capacity is no different from a laptop tucked away in a drawer. Altman’s 5% figure makes the most sense when read as a critique of utilization, not physical location.
I have always argued that not every task demands a top-tier model. Altman’s calculation holds up best under the assumption that everyone is running massive models. If a smaller model suffices for tasks like summarization or classification, running them on memory already sitting inside a PC does not consume any more of the world’s DRAM. What ought to bother us is not the DRAM inside a PC itself, but deploying an oversized model for a modest task—and leaving that memory sitting idle.
Closing
Altman’s 5% figure was less a rebuke of local AI users than a frustrated lament over the ceiling on aggregate memory capacity. In terms of utilization rates, his logic holds up. Yet pricing is already doing the work of allocation; the only question left is how quickly fab capacity can scale. With SK Hynix forecasting tight supplies through 2030, the memory premium baked into the prices of laptops and smartphones will remain a critical number to watch.
💬 Reader, if you run AI models locally, roughly how many hours a day does your machine spend actively running inference? Let us know in the comments, even with a rough estimate.
📨 If you have colleagues planning to upgrade their laptops or work PCs soon, share this issue with them.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Primary sources
- Cheeky Pint, “Why Sam Altman is against a single superintelligence”, 2026.10.29. ··· The original conversation that sparked today’s issue. The memory discussion begins in the “Compute” section (around the 25-minute mark).
- Cheeky Pint, “Why Sam Altman is against a single superintelligence (video, from 29:10)”, 2026.10.29. ··· The exact point where local inference and the 5% comment appear. Watch for yourself to see whether gaming ever comes up.
- IGN, “OpenAI CEO Sam Altman thinks it’s terrible for you to have RAM in your gaming PC”, 2026.10. ··· The article behind the screenshots that circulated across Korean online communities. I recommend reading it side by side with the video above.
- Samsung Electronics Newsroom, “Samsung Electronics Announces Q3 2026 Results”, 2026.10.29. ··· The primary source for the DS Division’s ₩106.5 trillion, the DX Division’s ₩0.8 trillion loss, and the annual CapEx of ₩84.4 trillion.
- SK Hynix Newsroom, “SK Hynix Reports Q3 2026 Financial Results”, 2026.10.28. ··· Details the projected 2030 supply crunch and the approximately ₩100 trillion shareholder return plan.
- Tom’s Hardware, “Micron warns HBM wafer penalty is widening with every generation”, 2026.8. ··· Covers the Hot Chips presentation highlighting that HBM3E consumes roughly 3 times more wafer area than DDR5, along with price-per-bit differentials. The foundation for the calculations in this piece.
- Seoul Economic Daily, “Sam Altman Meets 50 Samsung Executives to Deepen AI Accelerator and HBM Ties”, 2026.11.1. ··· Confirms the Yongin closed-door executive session and Vice President Richard Ho’s attendance.
Background
- SK Hynix Newsroom, “SK Hynix Reports Q1 2023 Results”, 2023.4. ··· Source for the Q1 2023 loss figure cited in the table. See the sheer swing over 3.5 years for yourself.
- Dealsite, “SK Hynix Turns Around Faster Than Samsung… What About Future Explosive Growth?”, 2023.10. ··· Cited for the Samsung Electronics DS Division’s Q1 2023 loss.
- StockHub, “Summary of SK Hynix Q3 2026 Earnings Call”, 2026.10.28. ··· Summarizes management remarks on the structural drivers of supply shortages and the direction of 2027 CapEx. An analyst recap, not an official company disclosure.
- Hankook Ilbo, “Semiconductors Account for 99% of Operating Profit: Samsung Steps Up Reinvestment but Struggles with Smartphone Losses”, 2026.10.29. ··· Quotes the CFO regarding component cost pressures weighing on the DX Division.
- Bizwatch, “Altman to Visit Samsung Following ‘AX Declaration’ Ahead of Meetings with Kakao and Naver”, 2026.6.11. ··· Outlines projections that Stargate could consume 900,000 DRAM wafers per month.
- The Korea Economic Daily, “Report on Sam Altman’s Visit to Korea”, 2026.6.11. ··· Reports on Samsung Electronics supplying HBM for OpenAI’s in-house silicon. Not officially confirmed by the company.
Recommended past issues
- Issue 183, “The 4-Year Agreement SanDisk Secured” ··· Explored why memory makers hold back on capacity expansion despite explosive demand, looking at the NAND flash side of the business.
- Issue 178, “You Can Download It; You Just Can’t Run It” ··· Mapped the boundary between models that can run locally and those that cannot, measured strictly by memory footprint.
- Issue 219, “The Next Battlefield for AI Chips Is Memory” ··· Traced how memory is stratifying into distinct hierarchies above and below HBM inside the AI data center.
📝 Glossary
Footnotes
-
Local inference: Running an AI model directly on personal devices like your PC or smartphone, rather than routing queries through corporate servers or the cloud. While data never leaves your device, the hardware itself must possess enough memory to hold the model. ↩
-
Free cash flow (FCF): The cash remaining after a company deducts capital expenditures (CapEx)—such as investments in factories and equipment—from cash generated by operations. Think of it as surplus funds available for dividends, share buybacks, or debt repayment. ↩
-
HBM (High Bandwidth Memory): Specialized memory created by stacking DRAM dies vertically in multiple layers and placing them directly alongside an AI accelerator. Its massive bus width is vital for AI compute, yet fabricating an equivalent capacity consumes vastly more silicon wafers than conventional DDR DRAM. ↩
Related issues
Keep the Keys Outside, Even for Superintelligence
NIST outlines 10 foundational tenets for managing AI agent identities, access permissions, and audit trails.
AI & TechDeepSeek's Super-agent: Another R1-Style Shock?
What R1 shook up wasn't performance — it was the price tag.
AI & TechWhen Meta's AI Errs, Its Terms Say You're Liable
Meta delayed its commercial terms to November 20, but the fine print already shifts AI-ad liability onto advertisers.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?