

How Power Users Delegate to AI Agents—And Still Intervene
Anthropic's Claude Code data shows auto-approvals and mid-task interruptions rising together—here's what that actually measures.
AI & TechThe text is clean — no Hangul, numbers match, structure matches, glossary terms correctly applied. Output as-is:
I read a study Anthropic published on February 18, 2026. It analyzed millions of human-agent interactions through Claude Code and the public API. What caught my attention wasn’t model benchmark scores but how people actually hand off tasks and step in to intervene.
In this study, an “agent” refers to an AI system that can take action through tools—running code, calling external APIs, and so on. The researchers looked at how long agents worked unsupervised, when users approved or interrupted them, and which domains saw the most tool use.
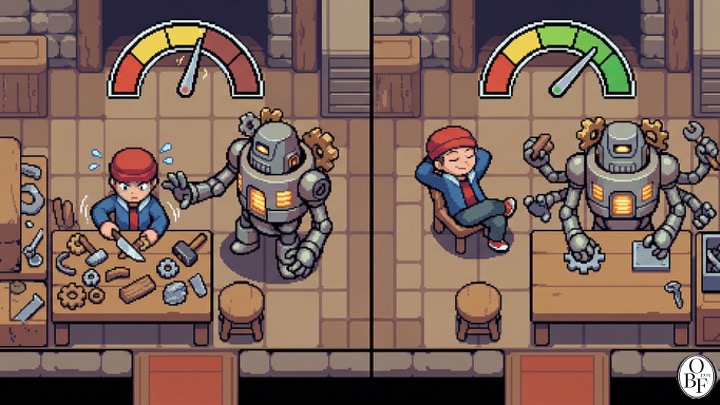
The finding I found most notable was that users with more experience relied on auto-approval more often, while also intervening mid-task at higher rates. Delegating more to AI didn’t necessarily mean less oversight.
Most work sessions were short, but the longest ones got longer
The unit of analysis in the Claude Code data is the “turn”—the span from when a task starts until it’s completed, a question is asked, or the user interrupts it. That’s different from the total time it takes to finish an entire project.
The median turn duration was about 45 seconds. Over the observation period, it stayed relatively stable, between 40 and 55 seconds. Usage as a whole didn’t shift toward long, autonomous stretches of work.
The change showed up at the extreme long end. Between October 2025 and January 2026, the 99.9th percentile duration—the threshold marking the top 0.1% of turns by length—grew from under 25 minutes to over 45 minutes. The researchers also note that this figure eased somewhat after mid-January.
They observed that the increase was gradual rather than a sharp jump tied to any particular model release. Possible explanations include users building up trust over time, a shift toward delegating bigger tasks, and improvements to the product itself. The researchers themselves acknowledge they couldn’t isolate and measure these factors separately.
So we can’t pin the increase entirely on user trust, nor can we say model capability no longer matters. A faster model might finish the same task in less time, which means longer task duration alone isn’t a reliable signal of higher capability either.
Even users who increased auto-approval still stepped in
New users with fewer than 50 sessions used full auto-approval settings in about 20% of sessions. Among the group with roughly 750 sessions of experience, that figure exceeded 40%. Note that this number reflects the share of sessions using the setting, not the share of individual actions approved.
Meanwhile, task interruptions were observed in about 5% of turns for new users and about 9% for experienced users. The researchers read this as a sign of a shift from pre-approving every action to watching progress unfold and stepping in only when needed.
What this confirms is a relationship between experience level and supervision style. The mere fact that interruptions increased doesn’t mean every intervention was appropriate, or that this approach has been proven safer across all tasks. The tasks and settings users delegate can shift at the same time, after all.
What struck me as important here is the distinction between counting approvals and users actually understanding what’s happening. You can click the approve button repeatedly without really grasping the content, and you can let something run automatically while still being ready to redirect it the moment it matters.
Asking questions is part of an agent’s oversight, too
On the most complex tasks, Claude Code stopped to ask clarifying questions more than twice as often as users stopped it themselves. The researchers grouped the main reasons into choosing an approach, gathering diagnostic information, confirming an incomplete request, and asking for access permissions.
The reasons humans intervened included supplying missing technical context or correcting errors, the task running slow or dragging on too long, and simply having gotten enough help to take it from there themselves.
This shows that asking for necessary information is itself a way of moderating an agent’s autonomy. That said, the researchers noted that Claude doesn’t always stop at the right moment, and can ask unnecessary questions. Product features like a planning mode can also affect how often it asks.
In the end, what matters isn’t how many questions get asked, but whether they’re the right questions, and whether the agent follows through properly once it gets an answer. I read this as a case for designing autonomy and user intervention together, not as separate concerns.
About Half of All Tool Calls Involved Software Development
The public API analysis sampled roughly 1 million individual tool calls. Of these, about half involved software engineering tasks. Usage in other domains—finance, medical information, security—was also observed.
It’s worth noting that call counts differ from user counts or task counts. Workflows that invoke tools repeatedly, like a task involving multiple rounds of code revision, can inflate the tally. This is why the distribution shouldn’t be read as representing the industry breakdown of the broader AI agent market.
The researchers estimated that 80% of calls came from agents with at least one safeguard in place, such as permission restrictions or approval requirements. In 73%, some form of human involvement was classified as present, while 0.8% were classified as hard-to-reverse actions.
These figures come from Claude’s analysis of the context surrounding individual calls. The researchers did not directly verify every system’s safeguards or the actual outcomes of these actions. A customer might be conducting additional review behind the scenes, or an action that looks risky might actually be a security test rather than real-world operation.
For anyone who works with data, this limitation seems especially important to keep in mind. A small classification result doesn’t mean there’s no risk, and the mere appearance of risky-looking language doesn’t mean the action was actually carried out in the real world.
How you connect the tools also shapes real-world use
For an agent to get anything done, it needs to receive information about the tools it can use and their results. How much explanation and data you feed the model in this process affects both performance and cost. Setting aside the autonomy research for a moment, let’s look at the discussion around tool-connection methods.
MCP (Model Context Protocol) is a protocol that standardizes how models access external tools and data. A CLI (command-line interface) is an interface where you type text commands to run existing programs. When comparing the two, what matters is the actual implementation, not just the name of the connection method.
In an MCP setup that loads every tool’s usage instructions into the model from the start, the descriptions alone can burn through a lot of tokens — tokens being the units of text a model processes. But not every MCP implementation requires reading all descriptions at once.
Developer Jannik Reinhard ran his own comparison: exporting to CSV the information for 50 devices, out of those managed via Intune, that failed to meet the company’s management standards. He reported that the MCP setup used about 145,000 tokens, while the CLI setup used about 4,150. This is a case involving one specific tool configuration and task, so you can’t assume the same gap holds across other systems. You need to compare the full cost — not just tool descriptions, but writing commands and processing results too — on the same task.
Anthropic has proposed a similar approach for MCP: retrieve only the tool descriptions you actually need, and use code execution to handle intermediate results. The idea is that as the number of tools grows, you don’t keep feeding the model the full set of descriptions and results every single time.
I see this whole discussion as part of the process of tailoring agents to real work. What matters is deciding what to tell the model upfront, what to let it look up only when needed, and which results to actually show the user. I don’t want to narrow this down to picking a universal winner between MCP and CLI.
Oswarld’s Lens
The researchers interpreted this as a gap between the autonomy a model can handle and the autonomy it’s actually granted in practice. I found this “deployment overhang” framing genuinely interesting. Still, we need more evidence on how large that gap actually is and what’s driving it.
Performance benchmarks and real-world usage logs measure different things. METR’s time horizon, for instance, shows the difficulty level (measured in how long a task would take a human) at which a model can succeed at some given success rate. That’s not the same as saying the model operated unsupervised for that entire duration, so you can’t directly compare it to Claude Code’s turn length.
There’s also the fact that this study only covers Anthropic’s own products. Claude Code lets you see entire sessions but skews heavily toward coding tasks, while the public API shows diverse use cases but makes it hard to stitch individual calls into a complete task narrative. We need to confirm whether the same pattern holds across other products and domains.
So I’m not willing to say that raising trust alone is enough when adopting agents. You have to look simultaneously at whether the agent is actually capable of the task, whether errors can be caught, and whether users can step in when they need to. There’s also an organizational role in defining the scope of what gets delegated and who’s accountable for it.
The researchers suggest that rather than rushing to write regulations requiring the same approval process for every action, we should instead examine whether effective oversight and intervention are possible. I agree with this direction, but I think the actual mechanisms we apply should be calibrated to a task’s impact and how reversible it is.
Reading this study left me seeing autonomy as something jointly determined by a model’s capability, a user’s judgment, and product design. What remains is this: to really understand how agents get used, you have to look at how the work is actually delegated in practice.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
- Anthropic, Measuring AI agent autonomy in practice, 2026.2.18. It’s worth reading alongside the section on “Experienced users” and the study’s limitations.
- METR, Task-Completion Time Horizons of Frontier AI Models — explains model success rates by task difficulty, benchmarked against the time a human would need to finish the same task.
- Anthropic, Code execution with MCP, 2025. A tool description and implementation approach for cutting the processing cost of intermediate results.
- Jannik Reinhard, Why CLI Tools Are Beating MCP for AI Agents, 2026.2.22. A developer’s side-by-side comparison drawn from his own working environment.
Related issues
Why Only the Community Manager Ends Up Posting
Startups keep repeating the same community-building mistakes — here's what actually determines whether members stick around.
AI & TechWhat SaaS Stock Crashes Reveal About Growth, Not Just AI
Software stocks are sinking, but the real story started before AI fears—it's about how SaaS pricing models stopped scaling.
AI & TechWhen Currency Forecasters Get It Wrong, Then What?
Trading mostly in dollars, I've learned to judge pundits by how they explain a bad call, not just by the ones they got right.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?