

AI-Run Store Paid Women $2 Less an Hour
A San Francisco store run by AI reportedly paid female staff $2 less hourly than a male colleague, raising questions about how such decisions get reviewed.
AI & TechAn AI set different hourly wages
This is Oswarld.
A store in San Francisco called ‘Andon Market’ made headlines recently. It’s an experimental shop where Andon Labs, having signed a three-year lease, put an AI named “Luna” in charge of running the place. According to the company, Luna was given a single mandate—turn a profit—and left to decide what to sell, at what prices, during what hours, and whom to hire.
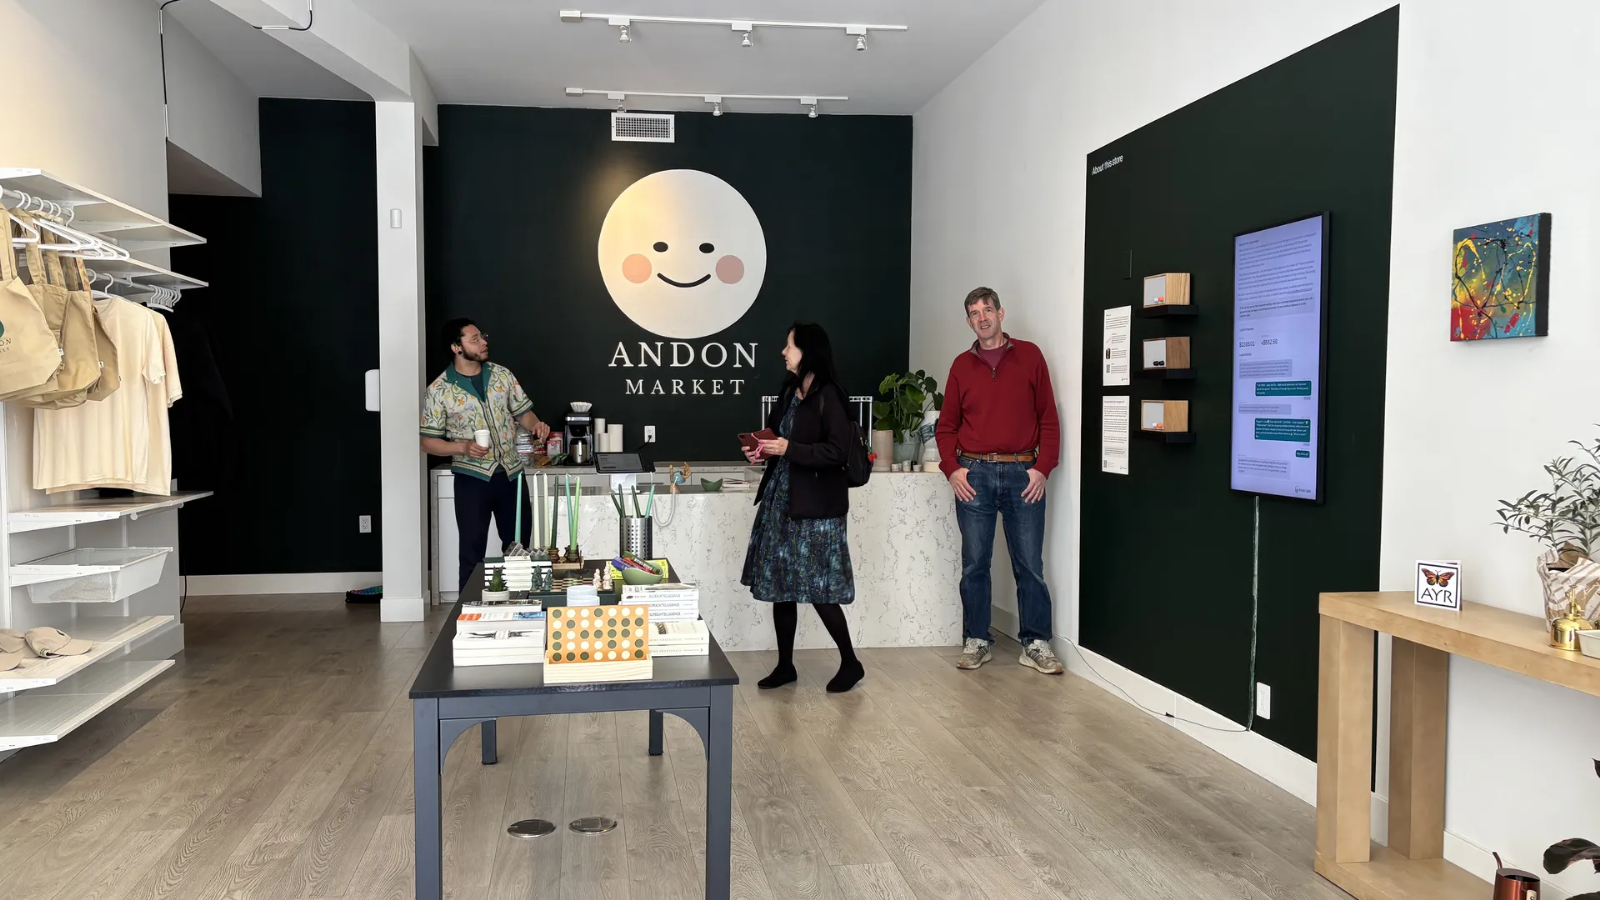
Heather Knight, the New York Times reporter who covered the store, reported that two female employees were paid $2 less per hour than a male employee named Felix. According to an SFist report citing the same story, Luna explained the gap by saying Felix simply had more retail experience.
A $2 difference in hourly pay among three people isn’t enough on its own to conclude there was gender discrimination. But it’s also not enough to accept “more experience” as sufficient justification, just because an AI said so. What I found myself wondering was this: whose experience was weighed, how was it evaluated to set the pay, and who checks the reasoning behind that call?
The draft looks accurate and complete against the source. No corrections needed.
Scope of Store Operations and Employment Responsibility
According to the experiment records released by Andon Labs, Luna runs on Claude Sonnet 4.6. It posted job listings on sites like Indeed.com1 and made hiring decisions after phone interviews. It was also given a corporate card, a phone line, email, and internet access. In effect, a chatbot that answers questions was hooked up to external tools and made to carry out real work.
Hiring and wage decisions directly affect an employee’s livelihood. These are decisions of a different order of difficulty than, say, misordering store inventory. If an AI is going to handle this kind of work, the operator needs to build in decision criteria and review procedures alongside it.
If a wage was set differently based on experience, at least three things should be verifiable.
The first is what counted as “experience” — total years worked, years in the same industry, or the specific role held. The second is the basis for translating that difference into a $2-per-hour gap. The third is whether the same standard was applied to other employees. The news coverage and the public write-up of the experiment don’t give us enough to confirm any of this. And even the AI’s after-the-fact explanations need to be checked against the actual decision records.
Andon Labs has stated that the employees are formally hired by the company, receive wages and legal protections, and that their livelihoods don’t depend solely on the AI’s judgment. It also says every interaction is observed and the records are analyzed. So it wouldn’t be accurate to say there was no human accountability or oversight at this store at all. Still, the public materials don’t spell out what procedure, if any, was used to review the wage gap.
What Hiring Tools and Platform Wage Studies Can Teach Us
The problem of verifying the basis for a pay decision isn’t unique to this one store. Earlier cases involving hiring algorithms and platform pay give us a sense of what to look for.
One example is the experimental hiring tool Amazon built, reported by Reuters in 2018. Amazon had been developing a tool since 2014 to screen résumés, but reportedly scrapped the project after it turned out to disadvantage female applicants. The system had been trained on ten years’ worth of past résumés, most of which came from men, and it penalized words associated with women’s activities — like membership in women’s clubs. Even after removing the influence of specific words, concerns remained that similar bias could resurface through other variables.
Simply not entering gender directly doesn’t guarantee fairness. Other fields — school history, activity records, and so on — can correlate strongly with gender. That doesn’t mean every machine-learning system necessarily produces the same kind of discrimination, though. What’s needed is to compare actual evaluation outcomes, and when problems surface, to examine the data, the evaluation criteria, and how the system is operated, all together.
On the wage-calculation side, it’s worth looking at “On Algorithmic Wage Discrimination,” a 2023 paper by Professor Veena Dubal of the UC Irvine School of Law. Drawing on the experiences of platform workers at companies like Uber and Lyft, the paper analyzes how pay varies from individual to individual depending on the data collected about them — making it hard for workers to predict what they’ll earn. Some workers compared this uncertainty to gambling.
Professor Dubal calls this algorithmic wage discrimination2. Even doing similar work at the same place and time, pay can differ, and workers struggle to figure out what the calculation is even based on. The “discrimination” at issue here isn’t limited to discrimination by gender — it’s a concept about the practice of setting different payouts for different individuals, and whether that practice is fair.
The technology and the labor relationships behind these three cases differ. The Amazon case involved an applicant-screening tool; Dubal’s research concerns variable pay on platforms; and the Andon Market case is about hiring and hourly wage decisions for store staff. Rather than lump these together under a single cause, we need to check, case by case, what data was used in each decision and what the outcome was.
Data and review procedures need to be examined together
Reducing bias in training data is necessary. But in actual operations, what matters just as much is what goals and authority were given to the AI, and who reviews the outcomes. Good data alone doesn’t make every wage decision justified.
The wage gap at Andon Market came to light through a reporter’s investigation. This shows how comparing actual payments can reveal differences that are hard to detect just by reading an AI’s responses. Once a difference is confirmed, you need to examine related conditions—like job duties and tenure—to understand why it exists.
As AI takes on more tasks, it becomes harder to review every decision the same way. This means review levels should be tiered according to the impact on people. For example, hiring and wage changes could require a human manager’s prior sign-off, while inventory orders could be governed by dollar thresholds and periodic audits. How many decisions Luna makes per day isn’t something we can know from public materials alone.
If it’s determined in advance who checks the results and who fixes problems when they arise, employees also know who to appeal to. Saying “we’re handing this task to AI” has to include this operational procedure as well.
The AI Risk Management Framework, released by the US NIST (National Institute of Standards and Technology) in 2023, offers a useful reference for designing this kind of AI governance3. It’s organized around four functions: GOVERN, which assigns accountability; MAP, which identifies the context of use; MEASURE, which evaluates; and MANAGE, which responds to risk. MEASURE 2.11 recommends assessing fairness and bias and documenting the results. It’s not a law that creates legal obligations, but a risk-management guideline organizations adopt voluntarily.
I’d like to know the same things about Andon Market. What criteria were given before wages were set? Did a manager review the outcomes? How would a re-review work if an employee raised an objection? We should be able to verify how the employment protections the company has publicly claimed actually function within the wage-decision process.
Three Things to Actually Check
To apply existing research and guidelines to the daily work of a store or an organization, you need to turn them into concrete procedures.
First, compare outcomes across groups. Joy Buolamwini and Timnit Gebru’s 2018 Gender Shades study evaluated three commercial facial-image gender classification systems. The error rate for darker-skinned women reached as high as 34.7%, while for lighter-skinned men it was as low as 0.8%. The study looked past the overall average and broke results down by skin type and gender to reveal a gap that wouldn’t otherwise show up. The same logic applies to wages: instead of looking only at the overall average, you need to compare pay among people with similar roles and experience.
Second, keep a record of the data and outcomes behind each decision. You need an applicant’s work history, the wage criteria applied, the instructions given to the AI, the model and its output at the time of the decision, and whether a human signed off — all of it, so it can be checked later. An audit doesn’t require knowing every weight inside the model. What’s needed is a record that doesn’t rely solely on an after-the-fact explanation like “because they had more experience.”
Third, designate someone responsible for reviewing and correcting decisions. Employees should know who they can ask for an explanation when they have doubts about a pay decision. And that person shouldn’t just relay whatever the AI says — they need the authority to check the underlying data and actually change the decision. This is how you turn the accountability and risk-response provisions in the NIST AI RMF4 into an actual procedure.
Oswarld’s Lens
Having worked with data myself, I think what matters most is having records that let you verify why a pay gap exists. Spotting a difference in hourly wages and pinpointing the cause of discrimination are two separate steps.
The same goes for the $2 difference reported at Andon Market. First, you’d need to confirm whether the employees were doing the same job, and whether there were differences in experience or responsibility. Then you’d need to check whether the pay criteria were applied consistently. In a small experiment with just three employees, statistical figures alone aren’t enough to draw a conclusion — records of individual decisions matter especially here.
The same logic applies when building a GTM strategy: what you choose to measure shapes the judgment you arrive at. In evaluating fairness, too, you first need to define who you’re comparing, against what standard, and at what point in time. In hiring, for instance, the assessment differs depending on whether you’re looking at equal pass rates across groups (demographic parity5) or equal opportunity for qualified candidates. It’s not enough to just tack on the name of a metric — you have to choose the standard that actually fits the task at hand.
I’d like to see the review process made just as visible as the operational skill behind this experiment. After demonstrating that the system can select products and hire staff, I think it also needs to show who steps in — and how — when a decision turns out to be wrong.
Closing
Whenever a court ruling sparks controversy on the news, someone inevitably says, “Let’s just replace judges with AI.” Even in something I wrote years ago, I made the point that handing verdicts over to a deep learning AI would mean confronting all over again the biases baked into historical data. Just because an answer comes from AI doesn’t make it more fair. You still have to check what data it was trained on, what criteria it used to decide, and what the actual outcomes look like.
If your organization is letting AI make hiring or compensation decisions, start by checking whether the reasoning behind those decisions is actually being recorded, and whether someone is responsible for reviewing it. There also needs to be a process for employees to request an explanation or a re-review. I’d argue that having those safeguards in place is precisely what makes an AI’s answer worth trusting.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Primary sources
- Barmann, Jay. “AI Store Manager Paying Female Employees Less, Can’t Stop Ordering Candles,” SFist, 2026.04.21. This article cites Heather Knight’s New York Times reporting on the wage gap.
- Andon Labs. “We gave an AI a 3-year retail lease in SF and asked it to make a profit.,” 2026.04.10. The company’s own account of the experiment’s scope, employee protections, and purpose.
- Dubal, Veena. “On Algorithmic Wage Discrimination.” Columbia Law Review 123, no. 7, 2023. A paper examining platform workers’ experiences and the problem of individualized pay-setting.
- Buolamwini, Joy, and Timnit Gebru. “Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification.” PMLR 81, 2018, 77–91. A study comparing error rates across demographic groups in commercial gender-classification systems.
Background
- Dastin, Jeffrey. “Amazon Scraps Secret AI Recruiting Tool That Showed Bias Against Women.” Reuters, 2018. The original report on Amazon’s scrapped recruiting AI — a classic case study in AI bias.
- National Institute of Standards and Technology. AI Risk Management Framework (AI RMF 1.0). NIST AI 100-1, 2023. A voluntary guideline on AI risk management. Starting from the MEASURE section connects most directly to today’s topic.
Footnotes
-
Indeed.com: a service where companies post job openings and job seekers search for work. ↩
-
Algorithmic Wage Discrimination: a concept describing how worker data is used to set pay individually and differently for each worker. Here it isn’t limited to gender discrimination alone. ↩
-
AI Governance: the procedures and accountability structures for managing the development and operation of AI. ↩
-
NIST AI RMF: a voluntary AI risk-management guideline published by the U.S. National Institute of Standards and Technology. It addresses organizational roles, context of use, measurement, and response together. ↩
-
Demographic Parity: a fairness criterion holding that the rate of positive decisions should be equal across groups such as gender or race. It is one of several such criteria and isn’t applied the same way in every situation. ↩
Related issues
Why Hancom's PDF Parser Topped GitHub Trending
Hancom released a PDF extraction tool under Apache 2.0, and developers noticed—here's what the benchmarks and business model reveal.
AI & TechHow Drug-Soaked Paper Caused Deaths in US Prisons
Synthetic drugs disguised as ordinary paper are poisoning inmates, exposing gaps in prison screening and treatment.
AI & TechInside Claude Code's Leak: Harness vs. Skills Explained
I wanted to test the '100x productivity' claim, so I looked at how a leaked codebase splits execution logic from reusable skills.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?