

Cheaper AI Video Doesn't Mean Cheaper Production
Veo 3's price cuts and Seedance 2.0 show that lower generation fees don't erase the planning, editing, and consent work still required.
BusinessWhat Changes in Video Production When Generation Fees Drop
The cost of making short AI videos is falling fast. In September 2025, Google cut Veo 3’s API generation fee from $0.75 to $0.40 per second, and Veo 3 Fast’s from $0.40 to $0.15 per second—cuts of roughly 47% and 63%, respectively. Google Developers Blog
What’s being compared here is the generation fee for the same model. It’s a mistake to set this figure directly against a production company’s quote. A production quote bundles in planning, filming, editing, and revision work, whereas the per-second API fee only covers what the model charges to generate the footage.
At $0.15 per second, generating one 8-second clip costs $1.20. Generate five clips at that length and you’d spend $6. That’s just the unit price applied to a calculation—it doesn’t mean you’ll land on the result you want within five tries. There’s still the work of picking a usable take, stitching it to other scenes, and getting the product name or captions exactly right.
That doesn’t make the price cut meaningless. It gives you room to test an idea in video form before a shoot, or to compare several directorial approaches. But when you’re building a budget, you need to add repeated attempts and editing time on top of the generation fee. You should also check whether a monthly subscription price divided by available credits is even comparable to the API rate.
Seedance 2.0 Takes Multiple Reference Inputs at Once
Seedance 2.0, which ByteDance introduced on February 12, 2026, is a model that takes text, image, video, and audio inputs together to generate both video and sound. The official announcement described multi-scene videos up to 15 seconds long with stereo audio output.
The feature worth noting for production work is the ability to assign a role to each reference input—instructing the model to take a character’s appearance from an image, camera movement from a video, and sound characteristics from an audio clip. The announcement also covered features for editing specific parts of a generated video or extending its length. Seedance 2.0 Official Launch Announcement
When I look at features like these, I care less about one polished demo than about how much easier revision gets. Whether the same character holds up in the next scene, whether you can change only the part you requested, and how long you have to wait for a regeneration—these are what actually shape production time.
It’s also better to compare models against the specific scene you’re trying to make. An ad that needs a product’s shape and text to be accurate, a video of someone speaking at length, and a scene with a lot of motion each have different requirements. What matters isn’t the cheapest single generation but the total cost of arriving at a usable result.
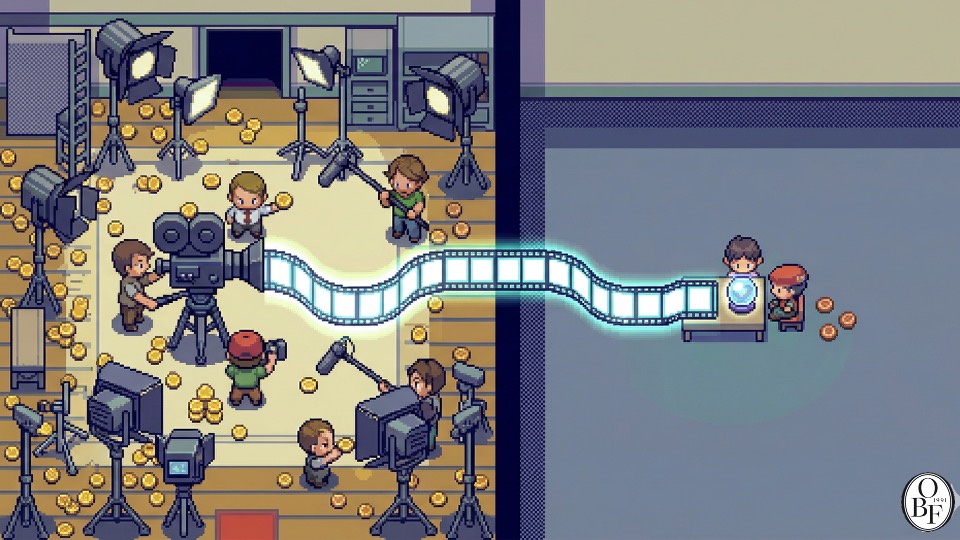
When a Photo Alone Produced a Familiar-Sounding Voice
Before launch, a different problem surfaced first in testing. According to a February 10 TechNode report, Chinese video creator Pan Tianhong input a photo of his own face and got back a result with a voice remarkably similar to his own—without having provided any separate voice sample. That’s what made it controversial.
This single case doesn’t prove the model can derive a voice from facial features. What was reported is one person’s test result, not a validated finding that anyone’s photo can reproduce their actual voice. Still, when a result resembles a voice the person never supplied, the questions become what data it was generated from and whether that person can control it.
The same article reported that Jimeng restricted the feature that references real people’s photos and videos, and introduced a process to verify a user’s own face and voice. This wasn’t an incident that emerged three days after the official launch—it’s a controversy that surfaced during pre-release testing. TechNode Report
ByteDance’s own February 12 announcement also states that making a video referencing a real person requires identity verification or prior lawful consent. That a feature is technically possible and that a person’s face or voice can be used freely are two separate things. Official Announcement’s Guidance on Referencing Real People
Oswarld’s Lens
There’s a pattern I’ve watched play out while building GTM strategy: once the cost of accessing a technology drops—as it did with cloud infrastructure or website building—simply being able to use that technology stops being a differentiator. I think the same shift is now underway in AI video.
As more people gain the ability to make video, what you show and from what perspective becomes the thing that matters. You first have to decide who you’re explaining which product to, what that person struggles with, and what they need to understand after watching. A cheaper tool doesn’t make that judgment call for you.
Working with data, I’m also attentive to how costs get calculated. News that the generation fee dropped and a result showing total production cost fell are two different claims. If reaching the desired outcome required many generations and long hours of editing, the per-second rate alone can’t explain the savings.
Videos that use someone’s face and voice add more to verify: whether that person consented, whether there’s room to mistake the video for something they actually said, and whether it can be edited or taken down if a problem arises—all of this needs to be built into the production process. My read is that as generation costs keep falling, the share of the work devoted to reviewing results and taking responsibility for them will only grow.
I welcome the spread of video production tools in itself. But I think the value you explain to a client should rest not on how many videos you generated, but on what those videos communicated and how polished they are.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References
- Google, Veo 3/Veo 3 Fast Price Cut Announcement, 2025.09.08
- ByteDance Seed, Seedance 2.0 Official Launch Announcement, 2026.02.12
- TechNode, Report on Restricted Face-Reference Feature and Voice Reproduction Controversy, 2026.02.10
Kwangseob Ahn is a professor in the Department of Business Administration at Sejong University and lead consultant at INLEVEL9. At the university, he teaches statistics and data analysis—covering areas like business data management and business analytics—while in the field, he leads GTM strategy and AI strategy consulting, designing the intersection of technology and business. He has published an academic paper on the memory architecture (HEMA) of AI conversation systems, and runs Daily Arxiv, a project that curates global AI papers daily. He completed a master’s program at Korea University’s Graduate School of Technology Management and holds a KMBA from Korea University. He is the author of the book 《Those Who Outsource Their Thinking: Homo Brainless》.

Related issues
Does a Doctor Next Door Shape a Child's Career?
Linked 1910 and 1940 US census records suggest neighbors' jobs matter—but the '41% higher' finding needs careful reading.
BusinessAI Made Tasks Faster. So Why Am I Still Working Late?
AI can save time on one task while quietly adding new work elsewhere—here's what the Jevons paradox and recent studies suggest you track.
BusinessKnowing Jensen Huang's Habits Won't Make You Jensen Huang
Judging founders and building GTM strategy: same effort, different results—learning a success story isn't the same as living it.
Society
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?