

Nvidia GTC 2026: How to Read Its $1 Trillion Pitch
I unpack Nvidia's Groq integration and the token-factory logic behind its infrastructure sales pitch.
AI & TechWhat Caught My Eye at GTC 2026
Nvidia’s GTC 2026 ran from March 16 to 19 in San Jose, California. In his keynote at the SAP Center, CEO Jensen Huang introduced the Vera Rubin platform along with an inference system built around Groq’s technology.
The $1 trillion outlook and the new products’ performance numbers got most of the attention. But what I noticed alongside all that was the way Nvidia bundles GPUs, networking, storage, and software into a single package. It read less like a pitch about how well the company makes individual chips, and more like a strategy of selling customers on exactly how to configure and run their entire data center.
Jensen Huang compared AI data centers to factories that manufacture tokens — the units AI systems use to process and generate text. In this framing, what Nvidia wants to emphasize is how many requests a fixed amount of power and equipment can handle, and ultimately, how much money that lets customers make. Below, I’ll walk through the business outlook, the Groq integration, and the cost math in turn.
What Does the $1 Trillion Outlook Actually Mean
Jensen Huang said he expects at least $1 trillion in cumulative business from Blackwell and Vera Rubin-related products through 2027. This is a different kind of figure from already-recognized revenue or a disclosed confirmed backlog. The previous $500 billion outlook covered the period through 2026, so the gap between the two numbers shouldn’t be read as revenue doubling over the same span.
According to CFO Colette Kress’s explanation as reported by DCD, this outlook covers Blackwell and Rubin products along with related networking. New standalone CPUs and Groq’s LPU are counted separately. Additional products could widen the revenue opportunity, but the scale of sales and adoption rates for each still need to be verified independently.
Customer composition matters too. Jensen Huang explained that roughly 60% of the business comes from the top 5 hyperscalers — large-scale cloud and data center operators. The rest includes general enterprise and industrial customers, plus sovereign AI1, the country-by-country AI infrastructure buildout.
Growing AI adoption in robotics, autonomous driving, and manufacturing could broaden the customer base further. At this GTC, BYD, Geely, Isuzu, and Nissan all announced adoption of DRIVE Hyperion. But a partnership announcement doesn’t translate directly into large-scale revenue — what matters is how far actual vehicle deployment and service operations progress.
Here’s what’s already been reported in earnings. For FY2026, which ended in January 2026, annual revenue came to $215.9 billion, up 65% year-over-year. Of that, data center revenue was $193.7 billion. The company guided next quarter — Q1 FY2027 — to $78 billion in revenue, with a margin of error of ±2%. This guidance does not include China data center compute revenue.
GPUs and Groq Devices Split the Inference Workload
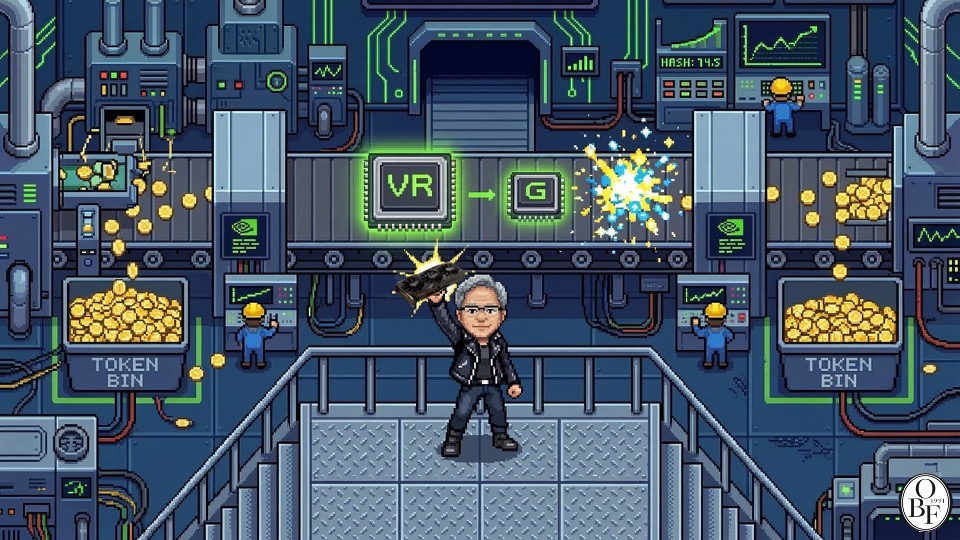
The fact that Groq’s technology has been woven into Nvidia’s products stood out too. The deal Groq officially announced on December 24, 2025 involves a non-exclusive technology licensing agreement plus some staff joining Nvidia. Media reports pegged the deal’s value at roughly $20 billion, but Groq stated it remains an independent company and will keep operating GroqCloud as a service.
The process by which AI generates an answer can be split into two stages: prefill, which processes the input, and decode, which generates output tokens one after another. The two stages differ in what compute and memory patterns they need. Nvidia is trying to boost efficiency by pairing each task with the device best suited to it.
The Rubin GPU leans on large memory capacity to handle many requests at once, while Groq’s LPU2 focuses on using fast on-chip SRAM3 to cut latency in token generation. It’s not that one device is unconditionally better—it’s that the nature of the workload assigned to each differs.
The Rubin GPU handles prefill, while for decode, the GPU and LPU work together. The setup routes attention operations4, which reference context, to the GPU, while part of the neural network computation—like the FFN—goes to the LPU. Dynamo software coordinates the division of labor and data transfer between the two devices.
The “up to 35x” figure Nvidia touts is a comparison of total inference throughput per watt against the GB200 NVL72, measured under the condition of generating 400 tokens per second per user. It means more requests can be processed with the same power draw—not that every single query gets answered 35 times faster.
Customers need to benchmark based on the response speed and concurrent user count their own service actually requires. A coding agent that needs fast responses and an overnight batch job processing large volumes of documents may call for very different configurations.
At the time of the GTC announcement, the Groq 3 LPX and Vera Rubin-based products were slated to ship in the second half of 2026. Whether the performance shown in the presentation materials holds up in real-world operation is something that will only be confirmed in customer environments after shipping.
Look at Hardware Price and Token-Processing Cost Together
What struck me most at this GTC was how Nvidia frames the value of its hardware. Beyond the price tag of a single unit, they want you to calculate how much power and time it takes to produce the response you want. Nvidia calls this “token economics.”
From a customer’s standpoint, even expensive hardware is worth considering if it can deliver the same quality of work at lower cost. But you have to add power, cooling, and operating expenses to the hardware price, and factor in actual utilization rates and how long the equipment stays in service. Peak performance alone can’t tell you whether a purchase makes economic sense.
Unlike services that simply serve up stored results, generative AI runs the model fresh every time a request comes in to produce an answer. Longer requests or ones that require multiple steps can drive up compute usage. If a task involves reviewing an answer multiple times or calling tools repeatedly, you need to add up the cost of that entire process.
How agents are used also affects cost. Breaking down the functions:
- Generation: producing text or code tailored to a user’s request.
- Reasoning: performing additional intermediate calculations or checks to arrive at an answer.
- Agentic work: calling tools, checking results, and carrying out a user’s task across multiple steps.
These functions can all be used together within a single service. When an agent calls the model multiple times or spins off sub-tasks, it can consume far more tokens than a chatbot that answers just once. This is why it’s becoming important for companies to set AI usage budgets by task. Not every request spawns dozens of agents, so you need to measure actual call counts and costs in real workflows.
This is also where Nvidia’s pricing defense comes in. A cheap chip, they argue, doesn’t necessarily mean low operating costs. I find this argument persuasive, but I don’t think the unit customers should be checking stops at token count. What matters is how much it costs to complete one unit of work at the desired quality. Generating a lot of useless answers quickly doesn’t help the business at all.
Oswarld’s Lens
This year’s GTC looks significant because Nvidia is widening the range of what it sells to customers. It’s no longer just GPUs — the company now bundles CPUs, inference chips, networking gear, and the software that runs all of it. That reduces the hassle of stitching multiple products together, but it can also raise the number of things a customer has to replace if they ever want to switch vendors. I’m watching this switching cost closely.
The Groq deal matters for how we read the competitive landscape, too. Groq’s inference technology had been seen as an alternative to GPUs, and now Nvidia has folded it into its own platform. Still, Groq remains an independent company, and other inference-chip makers are still in the field, so it’s a stretch to say Nvidia has eliminated a rival outright. What’s worth watching is which products customers can still choose separately, and which capabilities get bundled together.
China is another variable. At a press conference on March 17, Jensen Huang said Nvidia is resuming H200 production based on U.S. export licenses and orders from Chinese customers. Separately, Reuters reported — citing sources — that Nvidia is preparing a Groq-based product for sale in China, with supply expected around May. That second item isn’t a confirmed launch. I read it as an effort to keep China demand alive, but actual delivery will depend on approvals from both governments and the specific terms of each product.
Memory makers keep investing as well. In February, SK Hynix decided on roughly ₩21.6 trillion (~$15.6 billion) in additional investment to build Fab 1 and clean rooms 2 through 6 at its Yongin site, a semiconductor cluster in Gyeonggi Province, South Korea. Chairman Chey Tae-won, speaking at GTC, forecast that the wafer supply shortage could persist through 2030. The investment decision and the long-term forecast should each be weighed on their own; neither should be read as a guarantee that chip demand or profitability will keep climbing indefinitely.
The question I’m left with is how much of this spending end users can actually sustain. If cloud providers pull back on capital expenditure, or if paid demand for AI services falls short of expectations, Nvidia’s outlook could shift as well. I’ll also keep watching how the convenience of an integrated product plays out against customer choice and competition.
Closing
Watching this keynote, there are three things I want to verify going forward. Whether the $1 trillion forecast actually materializes into shipments and revenue, whether the division of labor between GPUs and LPUs cuts costs in customers’ real workloads, and whether the customers paying for these AI services get value that matches what they’re paying.
Nvidia is now proposing not just chips but the configuration and operation of entire data centers. When assessing this strategy, it’s worth weighing peak product performance alongside the actual outcomes customers realize.
If you’d like to check the presentation for yourself, the keynote and official technical materials are linked below. When reading the performance graphs, pay attention to the measurement conditions too — what’s being compared against what, and things like response speed per user.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
- NVIDIA, GTC 2026 Keynote, 2026.03.16: a presentation covering product roadmap and business outlook.
- NVIDIA, FY2026 Earnings Release, 2026.02.25: the official record of annual revenue and next-quarter guidance.
- NVIDIA, Vera Rubin Opens Agentic AI Frontier, 2026.03.16: details the platform’s composition and supply plans.
- NVIDIA, Inside NVIDIA Groq 3 LPX: explains the GPU–LPU division of labor and the conditions behind the “35x” performance comparison.
- Groq, Non-Exclusive Technology Licensing Agreement with NVIDIA, 2025.12.24: the official announcement regarding staff joining NVIDIA and Groq’s continued independent operations.
- DCD, Jensen Huang’s $1 Trillion Outlook and the CFO’s Scope Clarification, 2026.03.16.
- NVIDIA, BYD, Geely, Isuzu, and Nissan Adopt NVIDIA DRIVE Hyperion, 2026.03.16.
- Reuters, Jensen Huang’s Remarks on Resuming H200 Production, 2026.03.17; Report on Groq Preparing a China-Bound Product, 2026.03.17–18.
- Yonhap News, SK hynix’s Additional Investment in Its Yongin Fab, 2026.02.25; Reuters, Chairman Chey Tae-won’s Outlook on Wafer Supply, 2026.03.16.
Footnotes
-
Sovereign AI: an approach in which a country seeks to secure its own AI capabilities using its own data, language, and infrastructure. ↩
-
LPU (Language Processing Unit): the name of a processor Groq designed specifically for AI inference. ↩
-
SRAM: memory built into a chip that can be read and written very quickly. It has capacity and cost constraints that give it different trade-offs from other types of memory. ↩
-
Attention computation: the process by which a model calculates how much weight to give each part of the context when generating an answer. ↩
Related issues
Ask 70 AI Models the Same Question, Get the Same Answer
Different AI models can converge on strikingly similar ideas—here's what the Artificial Hivemind study found.
AI & TechCould a One-Cent Stamp on Email Kill Spam?
Adding a tiny fee or computational cost to every message might curb spam—here's what an old proposal gets right, and where it stalls.
AI & TechPrediction Markets Log Trades, but Insiders Stay Hidden
OpenAI fired an employee over insider trading in prediction markets, raising questions about what proof such cases actually require.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?