

Economists Are Using AI to Speed Up Research
Economists are using AI to code, clean data, and polish papers—raising real questions about speed versus rigor.
BusinessWhat “faster research” actually means
Economists are now using AI to write code, clean up data, and polish their papers. Some say this has freed up more time to think through the research question itself. Others worry it will lead to more half-baked papers and sloppier peer reviews.
The starting point for this piece is Soumaya Keynes’s FT column, “Economists have caught the AI bug”. I think this shift reaches well beyond economics—it touches how we produce and verify research and writing in general. So I want to separate two things: the time AI saves, and the quality of what comes out the other end.
Three Things AI Is Changing: Productivity, Scope, Verification
Let me break down the use of AI in economics research into three dimensions: time spent on tasks, the scope of what gets analyzed, and error-checking.
1. Cutting time spent on repetitive work
Reducing time spent on data cleaning, table formatting, and coding can free up time to think through research questions. Paul Novosad of Dartmouth, featured in a column by Noah Smith, says this has given him 5x more time to think. That’s a figure describing one researcher’s own experience — not an experimental result showing that research speed or output improved 5x.
The same column relays an observation from Erzo Luttmer, editor of the American Economic Review: roughly 25% of submitted papers now disclose AI use, mostly for editing or coding assistance, but there’s no clear shift visible in submission quality. This shouldn’t be read as a controlled comparison between papers that used AI and those that didn’t.
Smith also analyzed sentence structure in NBER1 working paper abstracts. He found that the trend toward shorter sentences continued after ChatGPT’s launch, while word complexity increased. Sentence length or the proportion of difficult words can reveal something about writing style, but they don’t directly measure a study’s accuracy or originality. This evidence alone isn’t enough to conclude that AI has made research better — or worse.
2. Analyzing and forecasting with more data
As the cost of analyzing text falls, the volume of material researchers can draw on grows. AI can be used to classify and compare material that’s too voluminous for humans to read line by line — earnings calls, policy documents, and the like. But whether the classification is accurate, and whether the same criteria hold across different time periods or groups, still needs to be verified by reading a sample directly.
In forecasting, there’s BISTRO, introduced by the Bank for International Settlements (BIS) in March 2026. It’s built on MOIRAI — a model that applies transformers2 to time-series forecasting — further trained on macroeconomic data. Users can feed in data like inflation or unemployment figures to generate forecasts, and compare results under assumptions about how oil prices might move along a particular path.
In a backtest using historical data, BIS researchers examined the persistence of the 2021 U.S. inflation surge. Starting from March 2021, the comparison models produced similar forecasts, but from June onward — once inflation had actually emerged — BISTRO captured the persistence of the upward trend better than AR(1) and MOIRAI did. This wasn’t a prediction made in real time back then. The researchers themselves describe it not as the answer to every forecasting problem, but as a tool for quickly generating baseline forecasts to compare against other models.
3. Verification — can AI catch errors in papers?
The third avenue is whether AI can help catch errors in research.
Refine, co-founded by Ben Golub of Northwestern University, is a tool that reads papers and flags mathematical errors, logical inconsistencies, and problems in empirical methodology. In a December 2025 talk at Markus’ Academy, Golub described cases where authors use it to check papers before submission, and where journals are piloting it as a supplement to human peer review.
Confirming whether AI’s flags are actually correct is still necessary work. Catching an error in an equation is also a different task from judging whether a research question matters in the first place. I’ve personally used and recommended Jenni, a research and writing assistant. But Jenni is focused on reading material, drafting text, and organizing citations — it’s better understood as serving a different purpose than a paper-verification tool like Refine, rather than lumped in with it.
When You Outsource the Whole Review Report
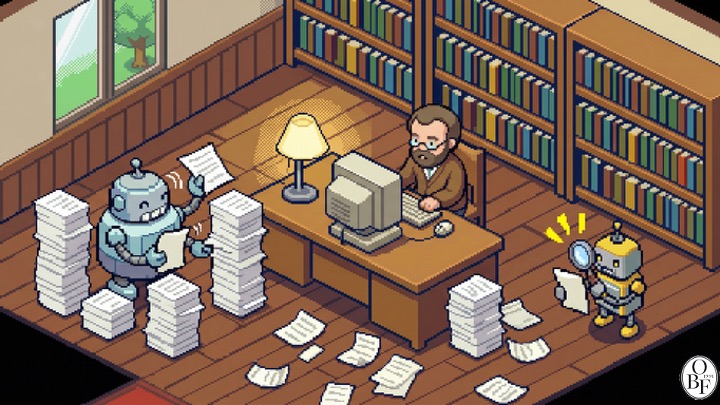
Even if AI helps catch errors, a different problem emerges when a reviewer skips reading the paper altogether and hands off the entire report-writing job.
What worries me is when the excuse that “AI already checked it” becomes a reason to skip human verification entirely.
In November 2025, the AI-text detection company Pangram announced that out of roughly 70,000 review reports submitted for ICLR 2026, about 21% were classified as “entirely AI-generated text.” Also, this figure isn’t confirmed statistics on how reviewers actually wrote their reports — it’s a detection model’s estimate based on the text itself. It can’t be used as proof that any particular reviewer acted in bad faith.
Still, the underlying issue remains: we need to be able to verify the content of review reports and who’s accountable for them.
As submissions increase, so does the burden on reviewers. Reviewing takes time and expertise, yet the compensation for that effort is limited. If a reviewer submits an AI-generated report without sufficiently checking it, the judgment originally entrusted to that reviewer can effectively go missing. This connects to the economic concept of moral hazard3, though it doesn’t mean every use of AI leads to this outcome.
Oswarld’s Lens
What comes to mind for me are Excel and PowerPoint. You can build a table quickly, but you still have to check separately whether the analytical method is sound; you can put together a slide deck with ease, but that doesn’t mean the explanation actually becomes clear. I think using AI to assist with research works the same way.
AI can cut down the time spent on drafting and checking work. But polished-sounding sentences can also paper over gaps in logic. In Golub’s talk, too, a concern comes up: once AI speeds things up, researchers may end up missing errors that used to surface only through long, careful review of the material.
What I focus on isn’t whether a researcher used a tool like Refine, but how they reviewed what it produced. If AI flags an inconsistency in a calculation or a definition first, the person can verify that flag and then spend more attention on the originality or contribution of the research itself. But that only works if you start from the premise that AI’s judgment can also be wrong, and go check the actual evidence.
This kind of division of labor won’t take hold simply because the tools now exist. If someone pastes in an AI-suggested sentence as-is and calls the review done, we could see more shallow, underdeveloped output — in papers and in blog posts alike. I think the time and standards we apply to review deserve just as much weight as writing speed.
Closing
AI can cut down on repetitive work, expand the material you can analyze, and help catch errors. But when you’re evaluating its impact, you need to look separately at time spent, volume of output, and accuracy of content. Writing something faster doesn’t automatically make it better research.
The same standard applies to code reviews or document reviews. You need to decide upfront what you’ll personally verify in AI’s output, and who re-checks it if an error turns up. What matters is not treating “AI checked it” as the end of verification.
BISTRO lets you examine its prediction process through the code and runnable examples the research team has published. With Refine, you can look at the published example reports to see what kinds of issues it flags. When comparing tools, I’d suggest looking less at how long or detailed the output is, and more at whether the problems it flags are actually correct and useful for making fixes.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
- Soumaya Keynes, Economists have caught the AI bug, Financial Times, 2026.
- Soumaya Keynes, A post introducing the column’s analysis and interviews.
- BIS, BISTRO: a general purpose oracle for macroeconomic time series, BIS Quarterly Review, 2026.03.
- Markus’ Academy, Modern AI for Economics Research: An Overview of Tools, 2025.12.18. A summary by the organizers of Ben Golub’s talk.
- Pangram, Pangram Predicts 21% of ICLR Reviews are AI-Generated, 2025.11.18. A detection-vendor’s analysis of the ICLR 2026 review reports.
- Pataranutaporn, P. et al., Can AI Solve the Peer Review Crisis?, 2025. An experiment covering four LLMs’ evaluations of economics papers and the biases tied to author information.
- Korinek, A., AI Agents for Economic Research, NBER Working Paper 34202, 2025.
Footnotes
-
NBER (National Bureau of Economic Research): a nonprofit economic research institution in the United States. Working papers share research findings before formal publication in an academic journal, and should be distinguished from results that have completed peer review. ↩
-
Transformer: a neural network architecture that processes relationships between input data using an attention mechanism. It can be applied not only to language models but also to numerical time-series forecasting. ↩
-
Moral hazard: a problem in which behavior changes because some of the cost or responsibility can be shifted onto someone else, in situations where it’s hard for others to fully observe one’s actions. Here, it connects to the difficulty of verifying how thoroughly a reviewer actually examined a submission. ↩
Related issues
TikTok's $10 Billion Fee to the U.S. Government
Reports say TikTok's US investors agreed to pay Washington $10 billion on top of their equity stake—here's what that fee actually buys.
BusinessFive Takeaways From China's 15th Five-Year Plan
Beijing's 2026-2030 blueprint ties tech self-reliance and AI adoption to a consumption push, with growth targets set year by year.
BusinessPerplexity's Gross Margin vs. Its Overall Losses
I look at how Perplexity classifies costs, converts free users, and expands features—and why staying power, not just paid conversion, matters most.
Business
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?