

Musk Admits xAI Distilled OpenAI Models in Court
Under oath, Musk said Grok's training partly relied on OpenAI's models, raising questions about what standard should apply.
BusinessWhat Musk Admitted
This is Oswarld. Today’s a special bulletin slipped in between our regular issues—so please share widely and nudge others to subscribe. Thanks, as always, for reading. 🙇 (If you haven’t subscribed yet, hit Subscribe!)
Yesterday (April 30), at a federal courtroom in Oakland, California, Elon Musk admitted that xAI had made use of OpenAI’s models. When OpenAI’s lawyer asked whether Grok’s training involved distillation1 of OpenAI’s models, Musk answered “partially”—adding that verifying one AI’s outputs using another AI is standard practice in the industry.
This is worth noting given that American AI companies have been the ones criticizing Chinese firms for unauthorized distillation. That said, this testimony alone doesn’t tell us what data xAI actually used, how much, whether it had permission, or under what contract terms applied. We also need to distinguish between training a model and merely verifying its performance. This admission is a good occasion to ask whether the same standard should now be applied to American companies as well.
What’s Actually Being Disputed in the Trial, and How the Testimony Unfolded
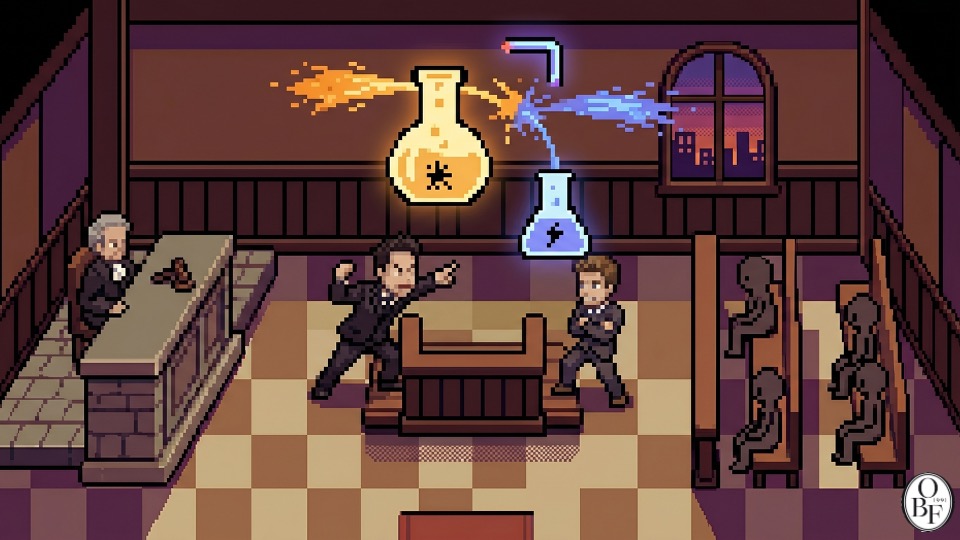
This trial concerns the lawsuit Musk filed against OpenAI in 2024. Musk claims OpenAI abandoned the nonprofit mission and commitments it made at founding, and he’s seeking the removal of executives, structural changes, and damages. OpenAI is contesting the claims. What’s actually in dispute here is the founding-era promises and the charitable purpose — not whether running a for-profit company is itself the problem.
On April 27, a nine-member jury was seated, and Musk’s testimony began on the 28th. He stated his position that what he had supported was nonprofit AI research.
On April 29, cross-examination covered Musk’s donations and his perception of how OpenAI had changed. According to AP reporting, the amount Musk contributed was roughly $38 million. He argued that OpenAI had strayed from the purpose he’d supported it for. This is a claim from one party in the litigation — the court has not yet ruled on it.
It’s worth looking closely at OpenAI’s current structure, too. Per the company’s own disclosures, even after the October 2025 restructuring, the nonprofit OpenAI Foundation still controls the for-profit public benefit corporation OpenAI Group PBC. Describing the nonprofit as having vanished and been fully replaced by a for-profit company doesn’t match the current structure.
Nonprofits and public benefit corporations (PBCs) also need to be distinguished. A PBC is a for-profit entity that pursues a public-benefit purpose alongside its commercial one. So it’s hard to treat xAI’s conversion from a PBC to an ordinary for-profit entity as the same issue as the OpenAI lawsuit, which concerns nonprofit assets and founding-era commitments.
On April 30, the third day of testimony, questioning turned to model distillation. Under questioning from OpenAI’s attorney William Savitt, Musk said AI companies generally make use of other companies’ models; pressed specifically on xAI, he acknowledged that this was partially true. The phrase “common practice” is Musk’s own characterization — it hasn’t been established that every AI company uses competitors’ models in the same way or under the same conditions.
Model Distillation as a Technique vs. the Terms Governing Its Use
Model distillation is a technique for using one model’s outputs or predictions to train another model. It’s widely used to transfer the capabilities of a large model into a smaller, cheaper one. The 2015 paper by Geoffrey Hinton2, Oriol Vinyals, and Jeff Dean is the best-known reference point, though model compression research predates it. Anthropic itself acknowledges that distillation, as a training method, is legitimately used.
The real issue is whose model was used, under what permission, and under what conditions. OpenAI’s service agreement, effective January 2026, includes a clause barring the use of outputs to develop competing AI, except under permitted exceptions. That doesn’t mean every instance of leveraging another company’s model is automatically a violation of the terms of service. You have to check the actual contract, the exceptions, and how the model was actually used. Whether the terms of service were violated, whether intellectual property was infringed, and whether any criminal law was broken are also separate questions that each need to be examined on their own.
On February 23, Anthropic announced that DeepSeek, Moonshot, and MiniMax used roughly 24,000 fake accounts to extract Claude’s capabilities through more than 16 million conversations. This figure is a combined total across all three companies, and it reflects Anthropic’s own investigation and claims. It shouldn’t be read as the usage figure for DeepSeek alone, nor as a fact established by any court.
A memo from the White House Office of Science and Technology Policy on April 23 similarly criticized foreign entities, primarily in China, for extracting the capabilities of U.S. models at scale using proxy accounts and circumvention of access restrictions. At the same time, it drew a distinction, noting that legitimate distillation is a necessary technique for building lighter, cheaper models. What matters isn’t the name of the technique itself, but whether access was unauthorized and whether restrictions were circumvented.
The same question applies to how American companies use these models
There’s a common question underlying both Musk’s answer and the suspicions surrounding Chinese companies: what’s permitted and what’s prohibited when using a competitor’s model in development? That said, this statement alone doesn’t confirm whether xAI engaged in fake accounts, restriction bypassing, or data collection at the same scale. Concluding that the two behaviors are entirely equivalent would require more evidence than this.
TechCrunch reported that OpenAI, Anthropic, and Google share information about unauthorized distillation attempts through the Frontier Model Forum3. Whether this kind of cooperation is applied strictly only to companies from certain countries remains to be confirmed. Meanwhile, the mere fact that OpenAI hadn’t responded to Musk’s remarks at the time of the article’s publication doesn’t mean it has decided to overlook violations by American companies.
To determine whether the same standard is being applied, the following points need to be compared:
- Did the company in question have authorization or a separate agreement to use the model?
- Did it bypass access restrictions or use fake accounts?
- Was the output data used for training or for performance evaluation, and at what scale?
- Do responses differ by a company’s nationality even when the contracts and usage methods are identical?
The ranking of AI companies Musk laid out in court should also be read as his own assessment. Just because he described xAI as a latecomer doesn’t mean we can conclude that Grok’s performance gains came from distillation, or that every latecomer company uses the same method.
Oswarld’s Lens
Having worked in corporate strategy, I’ve seen plenty of cases where a company’s stated principles diverge from its actual contract terms. So here too, I’m less interested in the “everybody does it” explanation than in the actual conditions under which the technology was used. Just because something is common practice in an industry doesn’t automatically mean it’s permitted under the contract. I think model providers need to spell out, in much more concrete terms, what counts as acceptable use by competitors and what crosses the line into violation.
We can’t tell from testimony alone why Musk gave the answer he did, or whether it was meant to pressure OpenAI. Nor can we conclude, just because the damages claimed are large, that this is merely a negotiating tactic dressed up as a lawsuit. Whether this testimony affects future disputes will depend on the actual usage records, the arguments both sides make, and how the courts rule.
Korean AI companies and policymakers should also examine how usage terms affect the development costs of later-moving firms. If terms of application differ by nationality, I believe that should be treated as a problem. But establishing that requires comparing the actual contracts and enforcement actions applied to domestic versus foreign companies. This single piece of testimony doesn’t prove that Korean companies specifically received unfavorable treatment.
The debate over domestic model development in Korea also needs clearer distinctions. Using publicly released weights in accordance with their license, scraping a competitor’s API outputs without permission, and training on one’s own data are three different things. Lumping them all together under a single label like “copied” or “industry practice” makes it harder to establish what actually happened.
Closing
What this testimony confirms is Musk’s partial acknowledgment that xAI used OpenAI’s models. It doesn’t settle the specifics of how they were used or whether that use violated any contract.
Going forward, I want to see what exact usage practices model providers point to when they criticize unauthorized distillation. The next question is whether they take the same action against American companies that used models the same way. Only that comparison lets us judge whether the stated rationale of protecting intellectual property actually matches how enforcement plays out.
If you’re a company building models, you need to check first which models, data, and license terms you’re actually permitted to use. The fact that a competitor used something a certain way doesn’t mean you have the same rights to use it.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Primary sources
- The Verge, “Elon Musk confirms xAI used OpenAI models to train Grok,” 2026.04.30. Reports on the exchange between Musk and the attorneys over model distillation.
- TechCrunch, “Elon Musk testifies that xAI trained Grok on OpenAI models,” 2026.04.30. Covers the testimony and the industry’s reaction.
- AP, April 28 trial coverage, April 29 trial coverage. Confirms the testimony schedule and Musk’s donations and claims.
- Anthropic, “Detecting and preventing distillation attacks,” 2026.02.23. The company’s investigation into unauthorized distillation by three Chinese firms.
- White House Office of Science and Technology Policy, NSTM-4, 2026.04.23. A policy memo distinguishing legitimate distillation from unauthorized extraction of model capabilities.
Background
- OpenAI, Services Agreement, effective 2026.01.01. Contains restrictions and exceptions on using outputs to develop competing AI. Actual disputes require checking which agreement applies to the user in question.
- OpenAI, Our structure. Explains the relationship between the nonprofit foundation and the for-profit public benefit corporation following the October 2025 restructuring.
- Hinton, Vinyals, Dean, “Distilling the Knowledge in a Neural Network,” arXiv, 2015. A paper that built on earlier model-compression research, based on a presentation at the NIPS 2014 Deep Learning Workshop.
Footnotes
-
Model Distillation: A technique in which one model’s outputs or predictive information are used to train another model. It’s widely used to build lightweight models, and the extent to which a third party’s model may be used depends on contracts and licensing. ↩
-
Geoffrey Hinton: A computer scientist who contributed to deep learning research and the 2024 Nobel Laureate in Physics. Along with Vinyals and Dean, he published a paper on model distillation in 2015. ↩
-
Frontier Model Forum: A consortium on the safe development and use of frontier AI, established in 2023 by Anthropic, Google, Microsoft, and OpenAI. ↩
Related issues
Steve Blank on the Startup Whose Market Moved While It Built Tech
A six-year-old portfolio bet shows how autonomy tech, customers, and competitors can all shift before a product ships.
BusinessHow Meta and Block Are Splitting Up Management Work
Both companies are cutting management layers while redistributing reporting, prioritization, and talent development to new roles.
BusinessWhy Bloomberg Terminals Still Dominate Finance
A Bloomberg command in an Iranian official's post got me asking why traders still pay for the pricey terminal.
Business
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?