

How Corporate Reports Shaped ChatGPT's Writing Style
ChatGPT now uses em dashes less often than humans do, and The Economist's 1.2M-word comparison reveals four real markers of AI prose.
AI & TechChatGPT now uses em dashes less than people do
These days, a single long dash in a piece of writing is enough to draw the comment “AI wrote this.” The mark English speakers call the em dash has quietly become treated as a machine’s fingerprint. But when The Economist lined up 1,200,000 words of human writing against AI writing and actually counted, it turned out that ChatGPT now uses the em dash less often than human writers do. In other words, spotting AI text by its dashes alone is already an outdated trick.
So what clues can actually flag AI writing today? And where did this style even come from? As it turns out, today’s AI writing style traces back to human writing—specifically, the kind written to be formally reviewed, like corporate reports and academic papers.
Four Features That Define AI Writing—Found by Comparing 1.2 Million Words
Let’s start with the experimental design. The Economist gave four models—ChatGPT, Claude, Gemini, and Grok—only a summary of its own articles and asked each to rewrite a piece on the same topic without web access. It then compared the resulting human and machine texts across 55,940 sentences and 1.2 million words—roughly the length of fifteen books. To rule out the possibility that its own house style was simply unusual, The Economist used as control groups the 2018–2022 average output of The New York Times, The Washington Post, and CNN, along with excerpts from bestselling novels published between 1950 and 2022.
The first finding is a changing of the guard among buzzwords. Delve and tapestry, once dead giveaways of AI writing, have all but vanished from the newest models. In their place, multisyllabic words like significant, increasingly, and consequences have moved in. In other words, catching AI by any single word has a shelf life measured in months.
The second finding is a reversal on the em dash. Among current models, only Claude uses more em dashes than humans do. ChatGPT, notably, used the fewest of any writer in the study—human or machine.
So what characterizes AI writing right now? It comes down to four traits.
The vocabulary runs heavy. All four models use more eight-plus-letter words than humans do—rare terms like interdependence, and scientific vocabulary like parameter or methodology. Nominalization1—turning verbs into nouns—is also pronounced: instead of the simple expand, the models reach for expansion.
Punctuation disappears. Commas and semicolons show up less than in human writing, and parentheses are almost absent. Because the models rarely quote experts, quotation marks are rare too.
Sentences run long, and the rhythm flattens out. The most overused word is the conjunction and. Sentence length varies less than in human writing, so there’s rarely a short, sharp sentence to break the flow.
The writing leans on rhetorical formulas. Claude noticeably overuses the “not X, but Y” construction more than humans do, and ChatGPT relies heavily on the rule-of-three list.
What ties these four traits together is a shortage of direct quotation and elaboration. No quotes, no quotation marks. No inserted asides, no parentheses. No reason to change pace, so sentence length stays flat. These are the statistical fingerprints of a text that narrates on its own, without drawing in anyone else’s words.
There’s one more important chart here. If you set the rate of typical “AI language” in an Economist article at a baseline of 1, ChatGPT’s 2024 output ran at roughly 6 times that rate—but the newest models have come down to somewhere around 2 to 3 times. In other words, each update is converging further toward human writing. Even the list I’ve just laid out may be outdated within a few months.
I covered, in the previous issue, the problem of detectors chasing an ever-shifting style and mistakenly flagging human writing as AI-generated. This time, let’s look at where this style actually comes from.
This Overlaps with What Orwell Flagged as Bad Writing Back in 1946
The Economist called this vocabulary list what George Orwell termed “pretentious diction.”
In his 1946 essay “Politics and the English Language,” Orwell dissected the bad writing of his era. The symptoms he identified: the habit of dressing up simple statements in complicated words and jargon, the tendency to stretch what a single verb could do into a noun phrase, vocabulary that puts on the cloak of scientific impartiality, and the belief that words derived from Latin or Greek carry more prestige than their native Saxon counterparts.
Compare this list with the characteristics of AI writing outlined earlier. Long Latinate words map onto Orwell’s “diction,” nominalization maps onto the noun-phrase habit he called “false limbs,” and scientific vocabulary maps onto the “cloak of impartiality.” In fact, in this very analysis, all four models used more Latin-suffixed words than the humans did. A list of bad-writing traits compiled 80 years ago maps almost exactly onto a list of AI writing traits in 2026.
There’s a part of Orwell’s diagnosis worth sitting with a bit longer. He didn’t think this style was purely a product of laziness. When you have to say something difficult to say, foggy words and the passive voice become a shield. Nominalization is the classic example. The moment “I decided this” becomes “the implementation of the relevant plan has been decided,” the agent disappears from the sentence. This is why formal register survives so stubbornly in government offices and corporations. It’s partly about sounding impressive, but it’s also useful for blurring accountability. The style that outlasted everything else in bureaucratic and corporate documents has now been inherited, wholesale, by machines.
Orwell didn’t just diagnose the problem — he prescribed a cure. Of his six rules, three are worth quoting directly: “Never use a long word where a short one will do. If it is possible to cut a word out, always cut it out. Never use the passive where you can use the active.” The four traits of AI writing outlined earlier are simply these three rules inverted.
What Orwell criticized wasn’t machines — it was the writing of bureaucrats, politicians, and academics. This list of traits existed first; the machines that write this way arrived 80 years later. So the question is: who taught the machine to write like this?
The cause: formal written training data and human feedback
There are two candidate causes.
The first is training data. The text the model grew up reading is what’s accumulated on the internet, and within that, what dominates isn’t casual conversation but edited, formal prose — papers, articles, reports, encyclopedias. Whether it’s the em dash or Latinate vocabulary, a lot of what’s been branded “AI’s tics” is really just the statistical habits of formal written language.
But training data alone doesn’t explain everything. Tom Yuzek and Gina Ward at Florida State University pulled 21 words — delve, intricate, underscore, and the like — that had surged in scientific abstracts, then traced why these particular words were being overused. They found no clear cause in the model architecture, the algorithm, or the training data. So the leading remaining candidate is the second cause: human feedback.
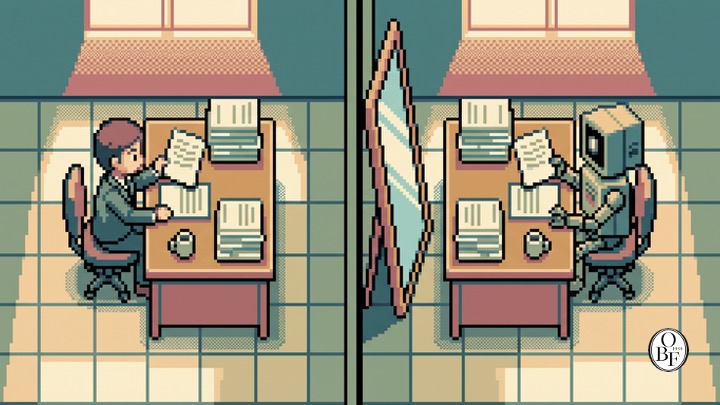 In the process called RLHF2, human evaluators compare multiple outputs from the model and pick the better one, and the model learns that preference. The problem is what people actually pick. In a snap judgment made in a few seconds, the writing that wins isn’t the accurate one — it’s the one that sounds impressive. Yuzek’s own explanation, quoted by The Economist, points the same way: the model picks up what people find impressive and drops what people dislike.
The em dash is a case study in just how fast a model can abandon something people dislike. Once the em dash became a punchline for mocking AI, ChatGPT’s use of it plummeted in the very next update. There’s an amusing scene an Economist reporter observed: the older model, when asked about its em-dash overuse, would banter about it while still peppering its answer with dashes — but the current model now primly replies that the mark should be used sparingly. Writing style is tracking public opinion on a timescale of months.
Let me clear up one misunderstanding here. Getting closer to human writing doesn’t mean the writing has gotten better. The Economist attaches the same caveat: even as the numerical gap has narrowed, AI prose still lacks clarity and elegance and keeps repeating formulaic patterns. What statistics like word frequency or sentence length capture is stylistic habit, not the quality of the writing. So the harder it becomes to spot AI text through these statistics, the more the real criterion ends up being the sheer polish of the writing. There’s one more barrier Yuzek’s team flagged: because how these models are built isn’t disclosed, it’s genuinely hard to dig all the way down to root causes.
To sum up: formal written language went in as training data, answers that sounded impressive got rewarded, and expressions that got mocked were scrubbed out in the next update. At every one of these three stages, it was people who set the standard. AI’s writing style wasn’t invented fresh by a machine — it was distilled from writing that people had already written and vetted. Watching the graph showing AI text edging closer to human text with every update, one might worry detection is only getting harder. What struck me more, though, is realizing how much of the writing style we’ve grown accustomed to using is already baked into AI’s prose.
Oswarld’s Lens
I’ve spent more than 20 years writing, reading, and getting sign-off on strategy consulting documents. If I think back on the common language of that world, it goes something like this: not “fix,” but “establish an improvement plan.” Not “use,” but “enhance utilization.” In Korean documents, Sino-Korean noun forms play the role that Latinate vocabulary plays in English. There’s an unspoken assumption running through the entire process of writing and approving documents that short, native-Korean verbs seem low-status.
And from what I’ve observed, the Korean that AI writes leans in exactly that same direction. “Through ~,” “from a ~ perspective,” “various,” “overall.” A good chunk of what people call “translation-ese” is actually “report-ese.”
That’s why Orwell’s list hit a nerve when I read it. Before it ever got around to describing AI prose style, that list was describing, point for point, the proposals I used to write. The practice of writing that sounds impressive enough to get approved came first — AI just learned, at massive scale, from the writing that people had already been selecting for. So I don’t think the answer is to go hunting for some list of tricks for “how to remove the AI smell.” Orwell’s principles weren’t designed to evade detection — they were guidelines for writing well, and that’s exactly what’s needed now. Short words. Living verbs. Cut it if you can cut it.
Closing
Here’s the summary.
- A single em dash can’t identify AI writing. The traits showing up in AI text right now are heavy vocabulary, nominalization, a habit of using fewer commas, parentheses, and quotation marks, and repeated rhetorical formulas.
- These traits overlap with what Orwell laid out in 1946 as the hallmarks of bad writing. This isn’t a newly invented style.
- The cause is training data dominated by formal written registers, plus human feedback that rewarded writing that sounds impressive.
Try one experiment today. Take a single nominalization in whatever document you’re working on and turn it back into a verb. Change “Establishment of an improvement plan is required” into “Here’s what I’ll fix.” The sentence gets shorter, and it becomes clear who is doing what.
If your workplace has a phrase that survives purely because it “sounds impressive,” report it in the comments. Once enough examples pile up, I’ll put together a “Dictionary of Korean Report-Speak” next time.
💬 Report in the comments any phrase that always seems to get your approval requests through 📨 Forward this issue to a colleague who writes reports for a living
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Primary sources
- The Economist, “How to spot AI writing,” 2026. Link ··· This is the analysis that forms the backbone of today’s piece. If you look at the original chart comparing 55,940 sentences, the differences between models come through much more clearly.
- Tom S. Juzek and Zina B. Ward, “Why Does ChatGPT ‘Delve’ So Much? Exploring the Sources of Lexical Overrepresentation in Large Language Models,” Proceedings of COLING 2025, 2025. Link ··· A study that couldn’t find the cause in architecture, algorithms, or data, and instead points to human feedback as the leading candidate. The experimental design section is the highlight.
- George Orwell, “Politics and the English Language,” Horizon, 1946. Link ··· The original text containing the six rules. It’s short, so I’d recommend reading the original.
Background
- Tom S. Juzek et al., “Word Overuse and Alignment in Large Language Models,” arXiv:2508.01930, 2025. Link ··· A follow-up study that reconfirms human-feedback training as the most likely contributor to lexical overuse.
Related issues worth reading together
- Did AI Really Write the US Declaration of Independence? ··· If today’s piece is about the player (writing style), that issue is about the referee (the detector). Read them together and you see the whole game.
- A Perfect Score at the Math Olympiad, No Proctor in Sight ··· A different branch of the same question: how do you verify AI’s claims?

📝 Glossary
Footnotes
-
Nominalization: The habit of turning a perfectly good verb into a noun — stretching “expand” into “pursue the expansion of.” It makes sentences longer and blurs who is doing what. ↩
-
RLHF (Reinforcement Learning from Human Feedback): A training method in which human evaluators choose the better of several model outputs, and that preference is then fed back into the model. The result is a structure that rewards whatever style catches the evaluator’s eye. ↩
Related issues
Why Harvey's Legal AI Chose a Chinese Model
Harvey trained its own legal model on Kimi K3 in just two months, and Washington cheered it as an American win.
AI & TechAn Agent Isn't a Product Until Someone Else Uses It
Getting AI to produce a result is easy—getting a colleague to keep using your agent or skill takes far more work.
AI & Tech51.8% of Korean Workers Now Use AI on the Job
Examining what surging adoption means for cognitive outsourcing, separating measured empirical shifts from vague anxieties.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?