

Twitch Quietly Turned On AI Training by Default
Comparing Twitch's new AI-training toggle with a free-cleaning startup in New York shows who actually gets to consent.
SocietyTwitch Turned On AI Training by Default
Twitch added a new setting yesterday. It’s called “Generative AI Training,” it sits at the very bottom of the Privacy & Security tab, and its status is: on. It means Amazon is training generative AI on Twitch broadcasts, and if you don’t want that, you have to go find the toggle yourself and switch it off.
When Chief Product Officer Mike Minton was asked why this wasn’t opt-in1, he answered plainly: if it were opt-in, nobody would turn it on.
Around the same time, in New York, people were lining up to let a stranger with a camera into their homes. The price of admission was one free cleaning.
What matters here isn’t that a new setting appeared. It’s the structure that setting sits inside. The person who clicks “agree” and the person who actually generated the data being used for training are two different people.
How far does Twitch’s opt-out for AI training actually reach?
What Twitch announced on August 12 wasn’t “we’re now starting to train on your data.” It was “we’ve added a setting that lets you opt out of training.” It sounds like a one-sentence difference, but the order is inverted. Training was already the premise; what’s new is the right to refuse it.
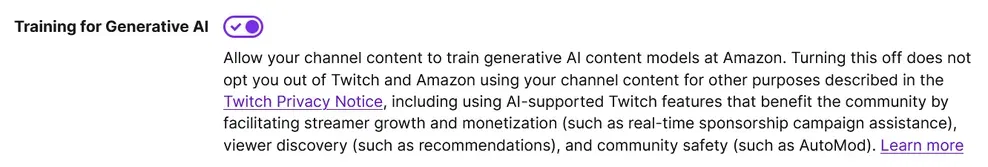 In fact, Minton, Twitch’s CEO, admitted at a media event in 2024 that Amazon does use Twitch to train AI. Training had already been underway for roughly two years, and the opt-out setting only arrived much later.
Even if you switch it off, not everything shuts down. Features like automated captions and Automod keep running. Twitch’s explanation is that these features retain data without generating new content from it. In other words, what this toggle blocks is generative-model training — not AI use in general.
The scope is broad. It covers live broadcasts and their chat logs, past broadcast replays, clips and highlights, and even text and images posted to a channel. A streamer’s entire multi-year archive is bundled into a single setting.
The backlash was swift. Within hours of the announcement, a forum post demanding a switch to opt-in gathered nearly 14,000 votes. Close to 3,000 people packed into a live stream where Minton tried to explain the policy, filling the chat with objections.
Up to this point, it’s a pattern we’ve seen on other platforms before. But two details in the announcement stood out to me.
First, whether your chat messages get used for training depends on the broadcaster’s setting, not yours. Chat messages you post on someone else’s stream follow that broadcaster’s setting. Even if you turn the toggle off on your own account, if the streamer whose broadcast you’re cheering on has left it on, whatever you type there is fair game for training.
Second, the broadcast screen also contains other rights holders’ work. What’s on screen includes copyrighted material belonging to game publishers. One gaming-industry analyst raised the question: what happens when a creator leaves the setting on while streaming someone else’s game? The setting lives on an individual account, but the data that flows into training under that setting carries another company’s copyrighted work along with it.
And when asked whether her own data had already been used for training, Minton said she didn’t know. Amazon, she said, hasn’t told even her what has and hasn’t been used. Which also means the company managing everyone’s consent can’t actually trace what happens to that consent afterward.
Free Cleaning in New York
There’s a company solving the same problem in exactly the opposite way.
Shift offers free house cleaning in New York. In exchange, the person who comes to clean wears a headset camera and films the work first-person. This footage, focused on hands and motion, becomes manipulation data2 to train home robots, and the company anonymizes it and licenses it to AI and robotics firms. The operator is Germany’s MicroAGI, and New York is just the starting point — they’ve said they’ll expand to San Francisco, London, Zurich, and Munich, and extend into plumbing and cooking as well.
 Let me put this in numbers. A standard apartment cleaning in New York runs roughly $150–250 per visit, or about ₩200,000–350,000 (~$150-250). My read on this structure is that the company is essentially footing the cleaning bill as the price of acquiring data. Most web text has already been scraped clean, and footage of an actually messy, lived-in home is genuinely hard to fake with a simulator.
The privacy disclosures are fairly thorough, too. Faces and names are automatically masked, and any personal information visible on screens, ID cards, papers, or phones gets blurred out. The camera is designed to focus on the cleaner’s hands and tasks. But the FAQ also includes a line noting that footage is shared with annotation3 workers during processing. In other words: even after automated anonymization, someone still sees inside that home.
The response is worth noting too. Reportedly, bookings hit the thousands within hours of launch. That figure comes from the company and trade press, though, not independently verified data. Still, the direction is clear — even on the condition of letting a camera-wearing stranger into the space right up to the bedroom door, people signed up.
Compare this to what Minton said. He argued that with opt-in, nobody would participate — yet in New York, once free cleaning was offered as compensation, people applied. What seems to have blocked participation wasn’t a lack of willingness to consent, but the absence of any offer of compensation for the data itself.
The Person Who Consents Isn’t the Person in the Data
Put the two cases side by side and the same structure shows up.
On Twitch, the person flipping the toggle is the streamer. But the data piling up in that stream isn’t made by the streamer alone. There are viewers typing in chat, and there’s the game company that fills the screen. One person gives consent, but the assets being handed over belong to several people.
At Shift, the person going through what amounts to a consent process is the homeowner. The person getting the free cleaning is also the homeowner. But the person wearing the camera on their head isn’t the homeowner — it’s the person who came to clean. And the destination that footage is aimed at is home robots, meaning the job that person is currently doing.
I want to head off a misunderstanding here: I’m not saying this structure amounts to exploitation. The cleaners get paid for their work. The company also runs a separate program that pays contributors per clip, and it stated that participants took home over $5 million in Q1 2026. Since that’s the company’s own disclosure, I’d take it with some caution — but the mere existence of that compensation is a point where this differs from Twitch.
What I want to flag is something else. Consent is obtained once, from an individual, but the data is generated on-site, where multiple people are present together.
In the home setting, there are at least three parties: the person who consented, the person who got filmed, and the person who will be affected later. In the broadcast setting, there are also three parties: the person who turned it on, the people who chatted, and the company that supplied the copyrighted content. But the only tool we have is a single toggle attached to an individual account. Trying to capture the circumstances of three different parties in one setting means that even switching it off only reflects part of the picture.
So why does the individual-toggle format keep showing up? Because it’s easy to build and easy to shift responsibility with. The moment a company offers a setting, it can say it gave people a choice, and anyone who didn’t turn it off gets treated as having consented. The way data actually flows stays exactly the same — only the burden of explaining it shifts from the company to the user. The user feels like they have a choice, but the range of what they can actually decide is narrow.
The contract structure makes this gap even wider. Shift explicitly states that it is neither the cleaning company nor the employer — it’s a technology platform. The people doing the cleaning are independent contractors vetted by partner companies. So there’s labor being filmed, but on paper, there’s no entity that actually employs that labor. Twitch is similar: consent is collected, but the company says it doesn’t know what Amazon actually used it for. In both cases, consent gets collected while responsibility gets scattered.
How Korean Platforms and Regulations Handle This
For Korean creators, this whole toggle debate might seem like someone else’s problem. Twitch shut down its Korean operations on February 27, 2024. There’s no switch to turn off, and none to leave on.
But the platforms that filled the vacuum are already running into the same problem, just from a different angle.
Chzzk’s “Magic Voice” feature reads donation messages aloud in the voice of a popular streamer. The extra revenue this generates goes to the streamer whose voice was used. It’s a structure where individual consent and settlement are built into a single feature. SOOP’s AI manager “Ssalsa” learns a streamer’s broadcast rhythm and speech patterns, then keeps the chat going while the streamer is away. This is arguably a step further, since what’s being learned isn’t content but a person’s manner of speaking.
The regulatory landscape points in a different direction too. Korea operates on a principle of prior consent for personal data processing, and the Personal Information Protection Commission issued separate guidelines in 2024 on using publicly available personal information for AI training. It’s not an environment where the American default-on approach transplants easily.
Still, having a regulatory framework doesn’t automatically solve the problem I described earlier. Mixed into the training data a streamer consented to provide are chat messages typed by viewers. The speech patterns an AI manager learns include the conversations that happened during that broadcast. The mismatch between who gave consent and who created the data is the same whether you’re in Seoul or New York.
Oswarld’s Lens
While putting together GTM strategies, I’ve reviewed data-sourcing plans more times than I can count. And there’s a scene I keep running into. A plan lists server costs, annotation costs, even labor costs down to the last line — but the cost of acquiring the source data itself is set at zero. The reason is simple: the users are already inside our service, so all you need to do is slip a clause into the terms of service.
Once you fix the procurement price at zero, everything that follows is already decided. Since the consent rate directly becomes the acquisition volume, the UI gets designed to maximize that consent rate. That’s why Minton’s remark doesn’t sound like a slip of the tongue — it wasn’t a mistake. It was a conclusion worked backward from a procurement target.
This is exactly why I put these two cases side by side. Shift offers cleaning as the price it pays to acquire data. It’s a business model that bets it can recoup that cost through data sales. Twitch, by contrast, sits on the largest library of creator video in the world and still hasn’t managed to put a price tag on its own content. So it chose to flip the default to “on” instead.
I think this difference is what will eventually split companies apart. A company that tries to secure data through terms-of-service language alone risks losing user trust down the road. A company that sets and pays a real price incurs cost upfront, but it keeps a basis for negotiating what to offer, and at what price, next time.
So the question we ask in practice needs to change too. Not “did we get consent,” but “does the unit of consent we obtained actually match the unit of the data itself.” If the data our service collects contains contributions from third parties who never consented, that’s a design flaw before it’s ever a legal risk.
Closing
First, I see Twitch’s default setting as an issue of consent, but also as an issue of what compensation is offered for data. Second, the New York case shows that people do opt in — when the compensation is made explicit. Third, in both cases, the people who consented and the people whose data is actually involved don’t fully overlap. Settings on an individual account can’t capture the will of everyone else affected.
I’d like to suggest one exercise this week. Pick a single point in a company you work for or a service you use where data gets collected, and list out everyone connected to it: the person who consented, the person who generated the data, and the person who will be affected down the line. If those three names don’t match, you need to check whose consent and whose rights are missing.
Is there a free service you use where you think, “I did consent, but I wasn’t actually the one who created the data”? Tell me in the comments which service, and which specific point in it. Once enough cases come in, I’ll organize them by type in the next issue.
💬 Leave your case in the comments in response to the question above · 📨 Share this with someone for whom this structure isn’t just someone else’s problem
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Primary sources
- Amanda Silberling, “Amazon will train on Twitch streamers’ content by default, unless they opt out”, TechCrunch, 2026. Link ··· This is the most detailed piece on the context around Minton’s remarks and how the announcement was framed.
- “Twitch under fire for new gen AI training system that harvests streamer data for Amazon”, PC Gamer, 2026. Link ··· The section on game publishers’ copyrighted material getting swept up along with streamer footage is where Chapter 3 of this issue starts.
- “How to stop Twitch from training AI on your streams”, Engadget, 2026. Link ··· Lays out exactly what opting out does and doesn’t turn off.
- shift, “Free Home Cleaning in NYC” official site and FAQ, 2026. Link ··· The filming method, anonymization process, and contractual relationship are all spelled out in the FAQ. Worth reading before Chapter 3.
- John Koetsier, “Physical AI Data Is So Valuable This Startup Cleans Your Home For Free”, Forbes, 2026. Link ··· The passage on the relationship between cleaning labor and robot training connects directly to today’s intersection.
Background
- Personal Information Protection Commission (Korea), “Guidelines for Handling Publicly Available Personal Information for AI Development and Services,” 2024. Link ··· Lets you check the standards Korea applies to AI training data.
- “Twitch Leaves Korea: How Will Domestic Streaming Change Going Forward?”, KISO Journal, 2024. Link ··· Sums up how Korea’s streaming landscape was reshaped after Twitch’s withdrawal.
Past issues worth reading alongside this one
- I Sold My Book for a Royalty ··· If today’s piece was about the structure of consent, that issue was about the price that comes after consent. Worth reading next.
- Cloudflare Gave Bots Names and Wallets ··· The opposite move: trying to make data-takers pay for what they take.

📝 Glossary
Footnotes
-
Opt-in / Opt-out: Opt-in means data is used only if the user actively consents; opt-out means it’s used by default unless the user turns it off. Participation rates swing dramatically depending on which one is set as the default. ↩
-
Manipulation data: Training data for teaching robots how to grasp, wipe, and move objects. First-person video capturing a human’s hands and gaze is the classic example, and the messier the environment looks like a real home, the more valuable it becomes. ↩
-
Annotation: The work of attaching labels like “this is a cup,” “this is a wiping motion” to raw data so it becomes usable for training. This is often done by a person watching the footage directly — meaning that even after anonymization, someone still watches the video. ↩
Related issues
The 1979 Report That Predicted Seoul's Overcrowding
I dug up a 47-year-old land-use report—and its warnings about Seoul read like today's headlines.
SocietyWhy 'Resting' Statistics Exclude Caregiving Youth
Caregiving youth are excluded from 'resting' statistics by definition, hiding how they actually spend their days.
SocietyPay Per Post, and Your Community Becomes a Vendor
Across 570,000 users and four market experiments, cash rewards boosted post volume but not quality—cashability decided everything.
Society
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?