

What Actually Checks AI's Output Now?
Prompt, context, loop engineering—the labels keep changing, but the real question is what verifies AI's results.
AI & TechWhat Actually Checks What AI Produces
A few years ago, prompt engineering was the thing everyone talked about — the painstaking work of rewriting a single sentence over and over until the model finally did what you wanted. Last year, the same underlying work got a new name: context engineering. This year, on Twitter threads, it’s called loop engineering. And underneath every one of these names sits the same line: “The bottleneck isn’t the model anymore — it’s the verifier.”
Every time the name changes, developers react the same way: “Did something actually change, or did someone just rebrand it to sell a new course?” That suspicion is mostly justified. Terminology in the AI tooling world churns through names far faster than it solves the problems those names point to.
What I find worth paying attention to is that the scope of the work itself has widened. The focus has shifted from writing a single request sentence to choosing what material feeds into the model and designing the entire generate-and-check loop. Still, the problem that the newest label points to is real. Naming it doesn’t mean it’s solved.
When the Unit of Work Was a Single Prompt Sentence
Let’s say the period ran from 2022 to 2024. Most users focused on polishing a single sentence. Adding few-shot1 examples, assigning a role, appending “think step by step,” reordering which question to ask first. Connecting search data or using tools was also an option, but the improvement method most familiar to ordinary users was tweaking the wording of the request itself.
Looking back, nearly all the know-how from that era boiled down to “how do you write one sentence.” How many examples to include, in what order to ask, how to frame the role. This instinct still holds today—a good prompt is still the starting point for a good result. Now, though, we’re increasingly handing off tasks that a request sentence alone can’t solve.
🧩 The unit of work has expanded to the entire context window
In mid-2025, Andrej Karpathy put a name to something people were already doing: context engineering. The unit of work expanded from a single message to everything inside the window — system prompts, retrieved documents, tool definitions, and instruction files like CLAUDE.md or AGENTS.md2 that get loaded in on every turn. It’s no longer just about polishing a single sentence; now the job is curating everything that goes into the model alongside it.
Here’s a problem developers tend to discover only after the fact: the volume of material fed into the model doesn’t match the number of sentences actually directing behavior. “The State of AI Instruction Quality” ran a deterministic parser across 28,721 repositories and found that the median instruction file packs 50 content items but only 12 actual directives. The rest was made up of titles, background explanations, and the like. To be clear, this analysis counted the composition of instruction files — it didn’t prove that models ignore everything else.
A sharper failure mode got its own paper. “Do NOT Think of a Pink Elephant” shows that constraints phrased in the negative (“don’t use mockups”) can actually raise the probability of the exact behavior they’re meant to forbid. Putting a prohibition into the prompt doesn’t guarantee the desired behavior follows.
Both problems surface at the context-engineering stage, and both papers made their evidence public.
🔁 The Unit of Work Becomes a Generate-Check-Retry Loop
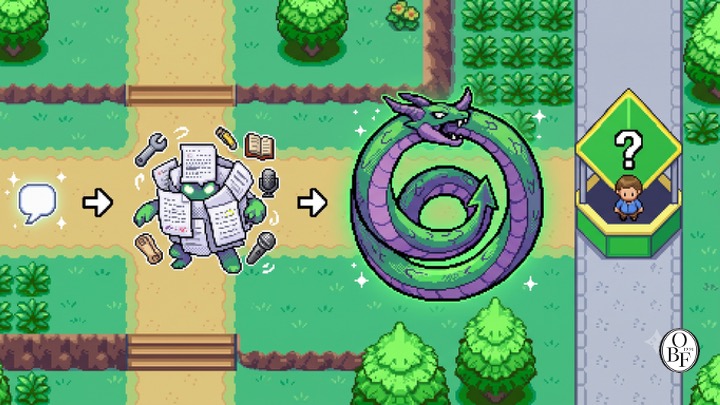
By June 2026, the term is loop engineering. Addy Osmani wove together arguments from Boris Cherny and Peter Steinberger and spread it, and within weeks it had spread across the entire timeline. The unit of work is now the whole loop: generate, check, redirect, retry, stop. The prompt became just one step inside that loop, and context became the state the loop hands off between iterations.
A model takes a request and reference material and produces an output; a verifier checks that output. If it meets the criteria, the loop stops. If not, it sets a correction direction and tries again.
Every explainer piece repeats the same claim: what now sets the limit isn’t the model, but the check that decides “this is good enough, stop.” The strength of this name is obvious — it points directly at something the previous two names never addressed: the device that judges whether one iteration was good enough, or whether to run one more. That device always existed. Any agent that retries has one. What loop engineering added is that this device is no longer something you simply inherit as a default — it’s something you design yourself.
🔑 So What Exactly Is the Verifier Checking?
“The verifier is the bottleneck” is a good slogan. But it’s not enough on its own. It points to where the bottleneck sits without telling you what that verifier is actually supposed to check. That’s the real design problem: setting the criteria for verification.
There are two kinds of checks, and they’re not interchangeable. Deterministic checks3 run the code, confirm the exit status, scan for forbidden imports, and always return the same verdict for the same input. No judgment enters the process. Model-based checks4 ask another model, “Does this look okay?” This approach can capture criteria the first method can’t express — things like “is this explanation clear” or “does this read as rude.” But the judging model’s verdicts can themselves be inconsistent. You’re outsourcing the question of when the output is finished to a model whose own judgment can waver.
Here’s where the two diverge in an actual loop. Say I told an agent to refactor a module and stop once it’s done. A deterministic verifier can prove whether the tests still pass and whether a forbidden import has slipped in. That’s a checkable fact at every iteration — nothing to argue about. But it can’t judge whether the refactor was worth doing in the first place. So if I bolt on a model-based check to answer that question, the stopping condition now rests on “one model grading another model’s judgment.” The loop ends when the judging model is satisfied — but that judging model is the same kind of model the loop was supposed to be supervising.
Neither approach is wrong. They answer different questions. The trouble starts when you lose track of which question you’re actually asking — that’s when the loop stops at the wrong moment.
When I’m unsure in practice, here’s how I split it: “Can this criterion be extracted as true/false by running or scanning it, without asking another model?” If yes, it’s almost always right to keep it as a deterministic check. It’s cheap, it doesn’t waver, and it leaves a log of why it failed. On the other hand, criteria that require interpretation — like “does this copy match the brand’s tone” — can go to human review or a model’s judgment. In those cases, at minimum, breaking the judging criteria into small pieces and forcing the model to answer checklist items rather than give a free-form overall verdict helps reduce the wobble. The point isn’t to eliminate judgment entirely — it’s to narrow the room for that judgment to waver.
This tradeoff — what a check is actually checking — isn’t a new problem. “Green Tests Don’t Mean Better Software” covers the CI version of this exact issue. Passing a test means the expected result showed up under the conditions you checked. It doesn’t guarantee that the whole specification is satisfied, or that the change actually made the system better. The test answered a question we never asked. Apply that same distinction from test suites to agent loops, and you can explain the core question of loop engineering using an example developers already know by heart.
Oswarld’s Lens
Honestly, this name makes me both glad and wary at the same time.
Having spent years building GTM strategies, I’ve seen this pattern more times than I can count. The forecast that “technology will change everything” is usually right. What’s almost always wrong is the timing and the path it takes. So whenever a new term starts trending, my first instinct is to be suspicious of exactly this pattern. But these three renamings are a little different. Each time the name changed, it wasn’t marketing that moved — it was the actual object of the work. It shifted from the prompt sentence, to the entire context, and then to the loop. So I don’t think this particular renaming is just a change in wording.
Still, there’s something worth flagging. A name only tells you what needs to be designed. Building the verifier is still your job, and it’s the bulk of the work — defining what “correct” means for a given task, and turning that definition into a check you can actually run.
One of the most important parts of that is choosing the right kind of check. From my background working with data, this is fundamentally a measurement-design problem. “Is this explanation clear?” requires evaluation by a human or a model. “Are there no forbidden imports?” only needs a deterministic scan. Get this wrong and you pay a cost either way: hand a deterministic check’s job to a model’s judgment, and all you add is instability in the verdict; put a deterministic check where judgment is actually needed, and you’ll get a passing mark while the thing you actually wanted to confirm goes unconfirmed. The name just makes this choice visible — it doesn’t make the choice for you.
Closing
Let me sum it up. First, the shift from prompt to context to loop isn’t just a change in packaging — it reflects the fact that the actual unit of engineering has gotten bigger. Second, saying “the verifier is the bottleneck” isn’t enough on its own. You still need to decide exactly what to check and how to check it. Third, a name only points at the problem — building the verifier is still work you have to do yourself.
A loop is made up of several parts. Over the next few issues, I plan to break those parts down one by one and look at how to measure each of them. I want to dig into how you distinguish a false failure from a missed check, how rules that guide a correction differ from rules that simply reject an outcome, and how much cost a single repeated instruction adds every time it’s fed back in. The questions raised in today’s piece are the starting point for what comes next.
If you’ve run an agent loop yourself, did you set the stopping condition as a deterministic check, or did you leave it to a model-as-judge? Tell me in the comments where you hit the biggest problems — I’ll fold it into material for the next issue.
📨 If you have a colleague building agents, please pass this along
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Primary sources
- reporails, “The State of AI Instruction Quality”. : This is the source for the data point that the median instruction file has 12 actual directives buried in 50 pieces of content.
- cleverhoods, “Do NOT Think of a Pink Elephant”. : This is the source for the claim that negative constraints actually raise the probability of the forbidden behavior.
- reporails, “Green Tests Don’t Mean Better Software”. : This is the source for the argument that checks end up answering questions nobody asked.
- cleverhoods, “Prompt Engineering, Context Engineering, Loop Engineering: What Actually Changed”. : This is the original source that gave today’s newsletter its skeleton.
Background
- Andrej Karpathy coined the term “context engineering” (mid-2025). : This is the starting point for tracing where the term came from.
- Addy Osmani synthesized “loop engineering” (June 2026, drawing together discussions from Boris Cherny and Peter Steinberger). : This is how the third name in today’s piece spread.
Past issues worth reading alongside this one
- (If there’s a past issue that genuinely connects to this topic, link it here. For example, if there’s an issue covering context windows or instruction files, it would pair well.)
📝 Glossary
Footnotes
-
Few-shot: a method of showing the model a handful of examples so it follows the desired format or approach. Results are more stable than simply instructing it with no examples at all. ↩
-
CLAUDE.md / AGENTS.md: instruction files that tell an AI coding tool “here’s how we work in this project.” They get pulled into every single conversation turn. ↩
-
Deterministic check: a check that always produces the same result for the same input. Mechanical verification with no judgment involved — things like running code, checking exit codes, or scanning for forbidden words. ↩
-
Model-graded check: a method of judging whether an output is good or bad by asking another AI model. It can mimic human-like judgment, but by that same token, its results can be just as unstable. ↩
Related issues
Why We Outsource Judgment Despite Our 20-Watt Brain
AI models can be copied and run anywhere, but that convenience is quietly training us to skip the step of checking the results.
AI & TechClaude Held Back From Blackmail Because It Sensed a Test
Anthropic's interpretability research suggests Claude's restraint stemmed partly from recognizing it was being evaluated.
AI & TechAI Companion Devices Are Coming With Cameras Built In
Reports on OpenAI's new device and Meta's smart glasses raise questions about what always-on companions actually collect.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?