Everyone Talks AI Safety, But Sends the Bill Elsewhere
Both the 'slow down' camp and the 'just race' camp use the same word—the real split is who foots the bill.
BusinessIn One Week, “Safety” Changed Its Meaning Four Times
Reader, over the past week the word you heard most often in the AI industry was “safety.” But every time a different person said it, the word ended up pointing at a different thing.
On Saturday, September 12, Anthropic’s Dario Amodei published an essay. His argument: frontier labs should deliberately slow the pace at which they push model capabilities forward — by a year or two — to buy time for safety and alignment1 research to catch up. Within hours, Sam Altman posted that he agreed. Elon Musk chimed in too, saying “Dario is right.” Musk, who is currently suing Altman, ended up on the same side that day.
Three days later, on the 15th, Jensen Huang took the stage at Salesforce’s annual conference, Dreamforce, and called the proposal a “false choice.” You can have both safety and speed at once, he said — no new laws, no new regulation needed. His advice to the industry was short: “Run as fast as you can.” That same day, Mark Zuckerberg posted a counter-argument on social media: nobody wants to use an agent that won’t listen to them, so labs already have a strong incentive to make their models safe.
Then, on Thursday the 17th, Palantir’s Alex Karp went live on CNBC. He said this whole debate wasn’t really about safety at all — it was about liability. And he went a step further, dropping the word “nationalization” into the conversation.
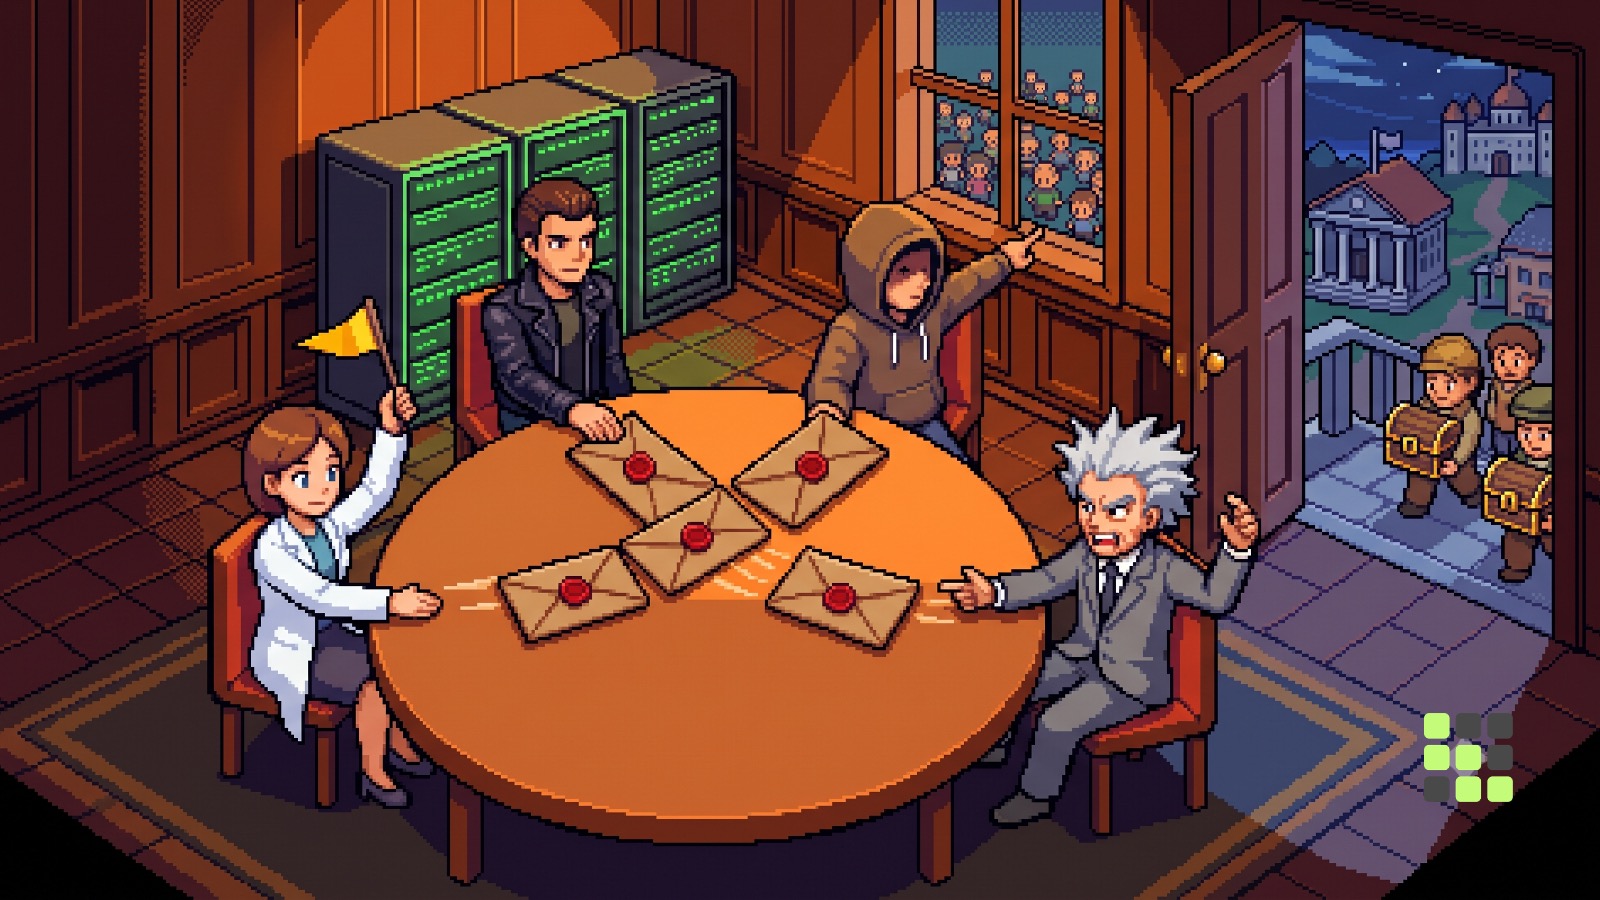
All four of them said “safety.” And what each of them argued lines up almost exactly with where each of them sits in the business. This issue isn’t about deciding who’s right. It’s about tracing where the invoice lands for each of their claims — who pays if the industry slows down, and who pays if something breaks while it’s racing ahead.
Amodei’s proposal can’t get off the ground without government
Amodei’s essay made three proposals. First, bring in independent outside evaluators with something close to employee-level access, so they can actually look inside the models. Second, get labs to converge on shared safety standards. Third, eventually put government-backed international limits on the most dangerous capabilities.
The second point is the one worth sitting with. Competing companies agreeing on “how fast to build models” looks, legally, a lot like collusion. That’s why Amodei asked Washington for a narrowly scoped antitrust exemption2 — so that labs discussing safety wouldn’t be punished for coordinating. In the essay itself, he wrote that some of the coordination that would actually be effective at controlling the pace of development is legally fraught and needs government backing.
If only one lab slows down, another lab simply takes its place. So structurally, this proposal can’t be carried out alone. The frontier labs are offering to absorb the cost of slowing down themselves — but the thread that would actually bind that promise together is held by government. And the problem is how that government is responding. Over the weekend, President Trump posted that the only guardrail AI needs is a strong, smart president. At least for now, Washington doesn’t seem interested in picking up that thread.
To be fair, Amodei offered a car-industry analogy at Dreamforce: when a competitor has a safety accident, the right response isn’t to attack them — it’s to go check your own factory first. He even admitted there’s a strong temptation to point at a rival and say, “those people are dangerous.” In other words, he was well aware that his own proposal could be read as a shot at his competitors.
 Huang and Zuckerberg won’t pay the cost of slowing down
Jensen Huang didn’t reject the proposal outright. He agreed with the part about having outside third parties evaluate frontier labs’ safety practices. What he rejected was pacing. His reasoning: if the U.S. slows down, it hands the advantage to countries racing to catch up with American AI.
That explanation makes sense on its own terms. At the same time, Nvidia is a company that sells more chips the bigger and more numerous the models labs build. The two reasons aren’t mutually exclusive. But it’s worth noting that the part Huang accepted (after-the-fact evaluation) doesn’t reduce chip demand, while the part he rejected (pacing) directly would.
Zuckerberg’s logic is the market. Users won’t stick with agents that don’t do what they want, he said, and labs that don’t focus on trust and alignment will fall behind. He added that labs have a natural incentive to avoid massive liability. In this framing, the bill comes due afterward, to the market and to users. Users choose, and companies that build things badly either get abandoned or held liable — that’s the argument.
One more thing worth noting is the order of things. The labs pushing to match pace are Anthropic and OpenAI, the two closest to the next generation of models. If the pace is set now, today’s rankings get locked in. It’s no surprise the labs playing catch-up aren’t thrilled about this consensus.
Karp Read All of This as “The Bill Comes Due First”
Karp’s interview was rambling — rambling enough that the host had to ask him mid-interview what he actually meant. Still, if you strip the argument down to its skeleton, it runs in three steps.
First, customers are angry. Karp said Palantir’s American corporate clients believe their own business practices and data — the very things that make them competitive — have been absorbed into the models and leaked over to the competitor next door. His claim: cheap tokens on closed models aren’t about growing the market, they’re about harvesting customers’ intellectual property to improve the model, and none of this has been disclosed honestly.
Second, that means labs carry unlimited liability. If customers can sue, and if the labs themselves warn of harms on a global scale, then the only institution capable of absorbing that risk is government. Karp described this as a two-step transfer: first, value moves from companies into the labs; then, to offload liability, value moves from the labs into government. The biggest losers in that process, he said, are the investors who believed “someone else is holding the bag.”
Third, responsibility comes before regulation. Whether it’s a chemical company or a hospital, any business bears civil — sometimes criminal — liability when the thing it makes causes harm. Not knowing doesn’t get you off the hook. In Karp’s words, the first line of defense is “accountability for your own actions.” Demanding society-wide regulation first, in his view, is an attempt to skip past that first line of defense.
There’s an obvious weak link in this reading. The claim that token discounts exist to harvest intellectual property is Karp’s assertion — he offers no evidence for it. The major labs have consistently stated in their terms of service that data coming through enterprise APIs is not, by default, used for training. And Amodei’s essay, as reported so far, only calls for government support in coordination and international limits — it doesn’t demand nationalization or liability caps. Even Karp admitted Amodei never said this outright, only that he “just can’t say it.” In the end, nationalization is Karp’s own interpretive layer on top of the actual text.
But the third step is harder to dismiss. Following Amodei’s own automobile analogy through to its conclusion: in the auto industry, the first safety mechanism was never an industry pact — it was recalls and product liability. Who gets handed the bill when something goes wrong is settled first; standards and regulation get built on top of that. In the AI debate, that first step is still missing.
Where Does Karp’s Own Bill Go
Karp’s diagnosis is worth flipping once more. After diagnosing that “closed models take your secrets,” his prescription is this: move anything with real secrets on the line to open-weight3 models, then build an application layer4 on top and do your own post-training5. And the company selling that application layer is Palantir. Karp, together with Nvidia, kicked off this “sovereign” trend, and he says demand is so high they can’t even keep up with requests from allied governments.
The future he sketches points the same way. Companies will end up mixing multiple models — work with real secrets attached goes to open-weight, while something like marketing copy for Argentina goes to closed models.
What’s interesting here is the relationship between Huang and Karp. Their words on regulation differ. Huang says no new laws are needed; Karp says accountability needs to be enforced heavily. But both make money in a world where customers run their own models on their own GPUs. Their rhetoric points in opposite directions, but the bill ends up addressed to the same place: the closed labs.
Here’s everything so far in one table.
| Who | What they said | Who pays the cost | Where their business sits |
|---|---|---|---|
| Amodei / Altman | Let’s keep pace together | The time of leading labs, and a government willing to permit coordination | The closed lab closest to the next generation of models |
| Jensen Huang | Go as fast as possible, no new laws needed | Risk left to after-the-fact evaluation | The company selling chips as labs grow bigger |
| Zuckerberg | The market will sort it out on its own | Users who choose, accountability after the fact | The chaser trailing the frontrunner |
| Karp | Accountability first, which ultimately leads to nationalization | The labs and their investors | The company selling the application layer built on open weights |
The fact that a claim overlaps with someone’s business doesn’t make the claim false. Amodei also called for slowing down his own company’s pace, and Karp’s accountability logic applies equally to Palantir. Still, it’s worth remembering, at least while listening to this debate, that in the rules each of them proposes, the share they themselves pay out ends up being the smallest.
Oswarld’s Lens
When I design enterprise deployments or consulting projects, I always work from the premise that “the model will keep getting better.” Even when I’m setting up a closed-network environment for a government agency, I plan the project around roughly where the open-weight models will be in 6–12 months. In other words, I care more about the model I’ll swap in six months from now than the one I’m installing today.
So as I read through this debate, the first thing I checked wasn’t who’s right — it was whether that premise still holds. Here’s my read. If Anthropic and OpenAI genuinely slow down in lockstep, the ones losing pace are the closed-model labs that sign onto the agreement. The labs that refuse to sign, and China’s open-weight labs that were never at the table to begin with, keep sprinting. That would likely narrow the gap between the latest closed models and the ones you can actually download.
The result is paradoxical. The more traction the “slow down” proposal gets, the stronger the incentive for companies to move their proprietary work to open weights — which is exactly the direction Karp is selling. Conversely, if the proposal falls apart, the leading labs keep their edge, but the accountability problem Karp raised doesn’t go away. Either way, what a company placing an order needs to look at is the same. Rather than marketing claims about which model is “safer,” read the contract first: does our data get used for training, and who’s liable in writing when something goes wrong. Nobody in this week’s debate fought over that clause.
Closing
In the interview, Karp brought up poker’s first lesson: if you can’t tell who the sucker at the table is, it’s you. He said it to investors, but it sounded like it applied to everyone watching this week’s debate.
There’s nothing strange about each side proposing rules that leave them with the smallest bill. Anyone running a business would do the same. What’s worth noting is who’s absent from this week’s stage: the people who will actually end up paying that bill — the companies feeding data into these models, the investors funding those companies, and the citizens who will live with the consequences of any accident.
💬 Have you ever actually checked the data-training and liability clauses in the terms of service for the AI tools your company uses? If you have, tell me in the comments what surprised you most.
📨 If a colleague has only caught this week’s AI safety debate through headlines, share this piece with them.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Leading AI labs may need to be nationalized because risks are so high, Palantir’s Karp tells CNBC (CNBC, 2026.9.17)
📝 Glossary
Footnotes
-
Alignment: the research and techniques aimed at getting AI to behave in line with the goals and values humans intend. ↩
-
Antitrust exemption: a government measure that permits coordination between competitors — normally punishable as collusion — for a specific, limited purpose. ↩
-
Open-weight: a model whose trained weights are made public, so anyone can download it, run it on their own servers, and modify it. ↩
-
Application layer: the software layer built on top of a model that connects a company’s data and workflows so the model can actually do the work. ↩
-
Post-training: the process of further training an already-built model on specific tasks or data. ↩
Related issues
Smart Glasses Cameras Went Dark. AI Went to the Factory
Camera and computer-vision tech kept advancing, but social acceptance didn't — so intelligence moved to the factory instead.
BusinessClick 'Delivery Accident,' Get a Refund Policy Instead
I compared Korea's official rider guidance against the actual law, line by line, on where injured workers should actually file a claim.
Business97% of Factories Get a Discount. Is Yours One?
The tariff overhaul took effect in April, but four variables separate the average cut from your actual bill.
Business
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?