

When Solving a Hard Problem No Longer Proves Expertise
A joint declaration from 25 Fields Medalists and a quiet shift in the consulting market are describing the same collapse.
BusinessThe declaration uses the phrase “proxy indicator”
On September 11, 2026, 25 Fields Medal laureates put their names to a joint declaration. Its subject: the way AI companies treat solving hard math problems as a performance benchmark, and how badly that clashes with what mathematics as a discipline is actually for. The signatories span generations — from Pierre Deligne, who won in 1978, to Wi Deng, a 2026 laureate — and the list includes the Korean-American mathematician Professor June Huh.
The heart of the declaration isn’t criticism. It’s a single-sentence definition: solving a problem is only a tool, a proxy indicator1, for measuring whether you’ve reached the real goal — conceptual understanding. Mistake the tool for the goal, and the tool ends up damaging the goal.
Two days later, by September 13, the number of signatories had grown to 4,432. Signing requires either an ORCID login or verification through an institutional email address. Even a document declaring that proxy indicators have collapsed still needed to bolt on a separate mechanism to verify that the people signing it were real researchers.
I couldn’t read this declaration as just an internal event in the world of mathematics. I’d already been watching the same fracture play out in a different market first.
Hard problems were mathematics’ measuring instrument
Famous unsolved problems in math have long done two jobs at once. One is internal. When a hard problem gets solved, that’s a signal that new methods and concepts were forged in the process — and mathematicians turn those ideas into shared tools through publication, debate, and refinement.
The other job is external. I don’t know what a Galois representation is, but I know Fermat’s Last Theorem got solved. Hard problems were a gauge that let even people who don’t understand mathematics recognize real skill.
What the declaration objects to isn’t the fact that AI can solve hard problems. It’s that when a solution gets rushed out into the open, proper write-up, citation of prior work, and the process of extracting and refining ideas all get skipped. The signatories write that this is where attribution and plagiarism problems arise. When a result appears but the people who could understand and build on it disappear, the gauge survives — but what it was measuring is gone.
Put simply: the danger mathematicians are describing is this — if you keep skipping the entire middle process and just grab the answer at the end, over and over, the essence and logic of mathematics itself starts to blur.
Say there’s a math problem with the answer being -1, 0, or 1. The odds of guessing right are 33.3%. A student who actually has the skill to solve it will write out the formula and reasoning; someone else will just guess the answer. If AI-style shortcut answers become the norm, the question becomes: who’s still going to bother studying math?
Mathematics is just the place where this is most visible. In markets where things carry a price tag, the cracks had already been showing for a long time.
The advisory market was already running on self-reporting
There’s a market called expert networks2 — places where investment firms and consulting firms buy hour-long calls with practitioners from specific industries. GLG says it has a pool of more than 1 million experts; GuidePoint claims more than 2 million.
On December 4, 2025, a research firm studying this industry published a survey of 1,368 experts who had taken part in advisory calls. About 31 percent of respondents said they had joined a call on a topic they weren’t adequately qualified to speak on — that’s roughly 420 out of the 1,368. The report identified three causes: self-reported expertise, the 24-to-48-hour turnaround requirement for filling requests, and keyword-based matching of people to calls.
Worth pausing on this: AI doesn’t even appear on the list of causes behind unqualified calls. Verification wasn’t broken by AI — it was leaning on self-reporting from the start. The same survey found that while clients pay $1,200 per call, the expert’s cut comes to less than 20 percent of that billed amount. From the buyer’s side, that gap was effectively the price paid for verification. Since this is a self-reported survey of industry participants, the numbers should be read broadly — but there’s no reason to doubt the direction they point in.
The compliance procedures that expert networks run before and after calls are thorough. But they exist to prevent the exchange of material non-public information. They aren’t built to measure whether a person actually did the work they claim, at the time they claim, or whether what they’re saying now reflects their own judgment.
Both sides of the market — buyers and sellers — are turning into models
Starting from the demand side, the change is happening fast. GuidePoint announced on March 26, 2026 that it had surpassed 100,000 expert interview transcripts, and on May 5 it plugged that library into Claude via MCP3. On August 26, it connected over 120,000 transcripts to Gemini Enterprise. The library grows by 5,000 transcripts a month, so the pile only gets bigger with time. AlphaSense and Tegus both advertise AI-conducted expert calls at 70 percent below the cost of traditional calls, and GLG offers AI-run calls too.
An answer obtained by asking a person becomes a transcript; the transcript becomes input for a model; and the next question goes to the model instead of a person. An hour, once bought, turns into an asset that keeps getting resold.
It’s not hard to guess which way prices will move. There’s no reason to buy a call for a question the existing transcripts can already answer, so the price of calls for common questions starts falling first. Conversely, a premium attaches to questions the library doesn’t cover — judgment calls nobody has put on record yet. This isn’t something the companies themselves have announced; it’s my own projection based on how the structure currently works.
The supply side is moving in the same direction. A large share of advisory work happens in writing, and written exchange is exactly the format a model answers best. Switching to video doesn’t change much either. As a result, buyers can’t easily tell whether they bought a person or a model, and sellers have no good way to prove they’re human. Both sides end up worse off, yet the transactions keep happening anyway.
So What Can Actually Be Proven
At this point, only one answer remains. Not the right answer — the experience of having lived through it. But how you certify experience is genuinely murky. Break it into three layers and you can see exactly where the gap is.
| Layer | What can be proven | Who verifies it |
|---|---|---|
| Affiliation and tenure | Where you worked and for how long | The company, school, or institution |
| Record of judgment | What you decided, when, and what turned out wrong | Right now, only you |
| Attribution of results | Whether the outcome was actually due to your judgment | No verification system exists |
The first row is verifiable but says nothing about ability. The third row speaks to ability but can’t be verified. So real verification comes down to the second row. For researchers, ORCID and citation records fill this gap — but practitioners have nothing equivalent.
The same logic holds outside advisory calls, too. Resumes, proposals, portfolios, interview answers — these are all proxy indicators, and being well-crafted no longer screens out anything. The era when a well-written document served as proof of competence was brief, and it’s over. Markets like Korea, where evaluating people through written materials and one-off presentations is deeply entrenched, will feel this shift more directly than most.
If you’re on the buying side, changing your question is the cheapest response available. For market forecasts or structural explanations, a model is faster and often more accurate than a human. But ask instead about a decision someone once opposed, a project that failed and the standard they changed afterward, or the part of their current answer most likely to be wrong — and the character of the answer changes entirely. A choice made under one’s own name at a specific point in time, and the price paid for it, simply doesn’t show up in a search. If you’re on the selling side, leaving that choice and its cost documented with a timestamp becomes, in itself, an asset.
Some read this declaration as a Red Flag Act
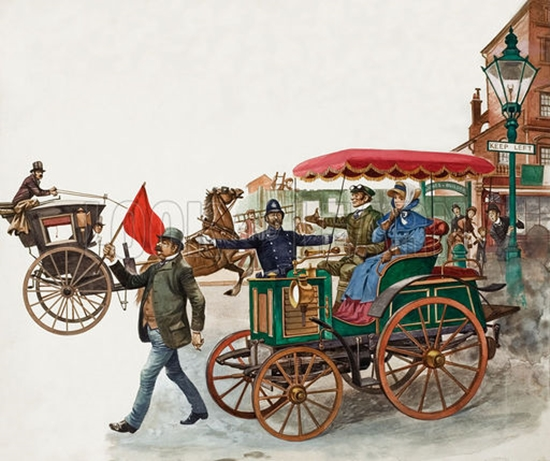
There’s an opposing interpretation too. In 1865, Britain passed a law requiring a person carrying a red flag to walk ahead of any automobile. It’s often cited as the classic case of an entrenched interest—the carriage industry—slowing down a new technology. Under this reading, the Fields Medalists’ declaration is ultimately just a protest from people about to lose their footing. There’s also a related claim floating around: that solving math problems will become an intellectual pastime, like chess.
Timing matters here too. In 2002, a math teacher named Paul Lockhart wrote a piece called “A Mathematician’s Lament.” His argument was that school mathematics had stripped away the process of discovery and kept only the results. Mathematics, in his view, isn’t the fact that a triangle’s area equals half of base times height—it’s the single-line idea that gets you there. School just makes you memorize the formula and calls it done. His conclusion: there’s no mathematics in math class. The same complaint existed 24 years ago, and back then the target wasn’t AI—it was the curriculum the math community itself had built. That makes it hard to write this off as a defense hastily improvised the moment a new technology showed up.
Bring Lockhart into the picture, though, and it doesn’t get any more comfortable for the math establishment either. The proceduralized mathematics he indicted—cranking out true/false verdicts according to a fixed format—is precisely what today’s models are best at. And it was the education system and academia that turned that format into the standard and graded it on exams. What got automated this time isn’t mathematical thinking—it’s the format we chose to grade instead of mathematical thinking. The advisory market is no different. It’s been buying and selling written reports built to a fixed template, so of course the template is what gets automated first. That’s actually why the first thing I did when I started my own consulting firm was decide not to sell reports. AI can write a report in no time anyway. Better to spend that time building a working PoC/MVP or running a workshop.
The “it’s just a pastime” camp actually reinforces this piece’s argument, if anything. Chess kept a human league even after losing to computers. But what that league sells is spectacle, not a certificate of skill. People pay money to watch players who are weaker than the computer compete. Saying that problem-solving becomes a pastime means its function as proof of skill drops away right there—and that’s exactly the process by which a proxy metric disappears. The only difference is that in the advisory market, there’s no one willing to pay admission just to watch.
Oswarld’s Lens
I serve as an expert advisor to firms like GLG and Silver Lake. Recently, the people who run those programs told me about a similar frustration: ever since LLMs became widespread, there’s almost no way left to tell experts apart. Written consultations end up getting answered by AI, and it’s true that even on video calls, more and more frontier models can respond in real time.
So now the only way left to verify an expert is experience—and I keep getting stuck on the fact that there’s no clear way to certify that experience. Which company I worked at, and for how long, can be confirmed, but beyond my own word, there’s no evidence for what judgments I made back then or whether those judgments were right. Short of filling in the second row of the table above myself, I still haven’t found any tool I can actually use right now.
One thing seems clear to me. What Fields Medal winners are trying to protect and what these advisory-program managers are wrestling with are the same kind of problem. In both cases, what’s being lost isn’t the quality of the output, but the ability to identify who produced it. The difference is that mathematics already has verification mechanisms—papers, citations, institutional affiliation—while the market for working experts has nothing but self-reporting. That’s why I think this market will collapse first, and more quietly.
Closing
Proxy metrics were always stand-ins — temporary tools we used because we couldn’t measure real ability directly. Solving problems, writing polished answers, explaining things fluently: all of it fell into that category. Now that models have taken over those temporary tools, what’s left is what someone has actually gone through and the choices they made in the process. The problem is that we don’t yet have a system to prove that.
If Reader is ever in a position to judge someone’s expertise, the safer move for now is to ask not about the quality of the answer but about the path that produced it. Whether more and more people actually stumble when asked that question — that’s something I plan to keep watching.
💬 The last time you had to judge someone’s expertise, what did you actually look at to decide? If you’ve got a criterion that failed you, I’d love to hear about that too.
📨 If you know a colleague who works with advisors or outside experts, send them this piece. Even just swapping in the list of questions here should make it immediately useful.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Primary sources
- Math and AI, “A Severe Misalignment of AI in Mathematics”, September 11, 2026. ··· The full text of the declaration, the list of 25 initial signatories, and the signing process all fit on one page
- Terence Tao, “A Severe Misalignment of AI in Mathematics”, What’s new, September 11, 2026. ··· Comes with a short firsthand account from one of the signatories on how the declaration came together
- Woozle Research, “The State of the Expert Economy 2025”, December 4, 2025. ··· Breaks down the denominator behind the 31 percent unqualified-response figure and analyzes its causes
- Guidepoint, “Guidepoint Launches MCP on Claude”, May 5, 2026. ··· The company itself explains the structure by which expert-call transcripts become model inputs
Background
- GLG, “Expert Calls”. ··· Shows what compliance procedures do and don’t check
- Paul Lockhart, “A Mathematician’s Lament”, 2002. ··· The original 25-page text. Just the first two pages, which open with a nightmare about music education, reveal the roots of this declaration
- Guidepoint, “Guidepoint Accelerates Enterprise AI Transformation with Gemini Enterprise”, August 26, 2026. ··· Lets you compare how transcript volume grew over just five months

📝 Glossary
Footnotes
-
Proxy: An observable indicator used to stand in for something hard to measure directly. Solving a hard problem stands in for understanding; a credential stands in for actual skill. ↩
-
Expert network: A service that brokers paid calls between investment firms or consultancies and practitioners in a given industry. GLG, Guidepoint, and AlphaSights are leading examples. ↩
-
MCP (Model Context Protocol): A connection standard for attaching external data or tools to an AI model. Used when a company wants a model to query its own proprietary data directly. ↩
Related issues
How You Sell GPU Compute Changes Your Margins
Buying servers, subleasing them, or billing by API token each demand different upfront cash and payback timelines.
BusinessWhat Counts as One 'Resolution' in AI Support Pricing
Fin charges $0.99 per resolved ticket, but the definition of "resolved" decides what you're really paying for.
BusinessSamsung and ASML Both Bet on the Same AI Startup
Mistral's last two funding rounds were both led by companies that own factories, not venture funds.
Business
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?