

The Bank App That Asked for Face Scans Three Times
Shipping speed keeps climbing while nobody gets credit for the unglamorous work of fixing what's already broken.
AI & TechThe Bank App That Asked for Face Scans Three Times, and a Congratulatory Post
Last week I read a developer’s account of a string of small tech failures he’d hit in a single stretch. A banking app made him verify his face three separate times just to reach the payment confirmation screen. A Slack window popped up late, stole focus mid-keystroke, and the command he was typing into his terminal got fired off into a group chat instead. He filled out a long warranty-repair form for his refrigerator, only to have it fail at the very last step. His car’s infotainment system, after a recent update, now reboots itself while he’s driving.
One detail he added stuck with me. A few months earlier, the PM who’d led the redesign of that car’s operating system had posted on LinkedIn celebrating the great work the team had shipped. The user fighting that same product every single day can’t stop thinking about that post.
The engineering team scores itself on how fast it shipped the feature. The user just experiences the bugs. AI has largely solved the problem of “code can’t be written fast enough.” What it hasn’t touched is the problem of “nobody rewards the person who fixes it.” When shipping speed accelerates but maintenance doesn’t keep pace, the gap between what teams measure as success and what users actually experience as quality only widens.
Throughput has genuinely gone up
You can’t blame AI for all of this. Speed really has increased.
Google’s DORA team surveyed roughly 5,000 tech workers worldwide for its 2025 report, and 90% of respondents were using AI in their work, with a median daily usage time of 2 hours. And unlike the 2024 survey, this year’s data showed a relationship where higher AI adoption correlated with gains in both software delivery throughput and product performance, together. It suggests teams are learning where and how to apply these tools.
Individual data points tell a similar story. GitClear, which analyzes code change histories, released a report in January 2026 showing that the group of developers who used AI most heavily produced 4–10x more output than non-users. But there’s an honest caveat attached. Much of that gap traced back to pre-existing individual skill differences that predated AI, and when you compare the same person against their own past performance, the speed gain was closer to 25%. This reads less like “AI made people skilled” and more like “the people who were already skilled picked up AI first.”
The problem lies in another finding sitting right alongside this one in the same DORA report. Higher AI adoption also came with higher deployment instability1. That means more unplanned deployments triggered by failures. DORA sums up this combination in a single word: amplifier. AI amplifies the strengths of organizations that were already running well — and it amplifies the flaws of organizations that were already struggling, just the same.
Refactoring is disappearing, copy-paste is surging
So what’s actually being amplified? GitClear’s 2026 follow-up study gets fairly specific about this. It’s a dataset that tracked 623 million code changes from 2023 through 2026, broken into eight signals. The direction is consistent across the board.
The most striking finding is the disappearance of refactoring2. The share of total changed lines classified as “moved code” — meaning existing code that’s been cleaned up and repositioned — fell from 21% in 2022 to 3.8% now, in 2026. Over the same period, the share of copy-pasted code rose from 9.4% to 15.7%. Back in 2022, developers chose to clean up code twice as often as they chose to paste it; now that ratio has flipped, with pasting winning out by roughly 5 to 1.
Other metrics point the same way. Duplicate blocks of five or more identical lines have jumped 81% compared to 2023 — the highest rate on record. The frequency with which newly written code calls other functions in the existing codebase has dropped 35%. That means new code sits isolated in its own file, disconnected from the rest of the codebase. And the share of work devoted to reopening code untouched for over a year — to clean it up or discard it — fell from 1.7% to 0.46%, a 74% decline.
It’s easy to see why this matters if you picture a single duplicated block. If a five-line block is scattered across ten different places, whoever fixes one of them automatically inherits the obligation to track down the other nine and figure out “does this need to change here too” — even in files and domains they know nothing about. It’s a structure where saving 30 seconds now means other people spend far more time, years later, repeating the same verification work.
GitClear calls this the “maintainability gap.” And the report sums up the core issue this way: the problem isn’t that AI writes bad code — it’s that today’s default workflow is designed to produce one happy path, one passing test, one closed ticket. Work that’s immediately visible and quickly wrapped up gets rewarded, while cleanup work that stays out of sight and keeps getting deferred comes back later at a much higher cost.
So Why Doesn’t Anyone Fix It
Given how good the tools have gotten, why does no one pay down this debt? The developer quoted earlier wrote the answer as an imagined announcement.
“This quarter, we’re not shipping any new features, and there’s no redesign planned. We’re focusing purely on bug fixes.”
How many organizations could actually put that sentence on a quarterly planning slide? I’ve hardly seen any. The reason is simple. New features come with a demo, a story you can present, a line you can put on a performance review. Stabilization, when it goes well, leaves behind only the fact that nothing broke. There’s no deliverable to show for the work done right.
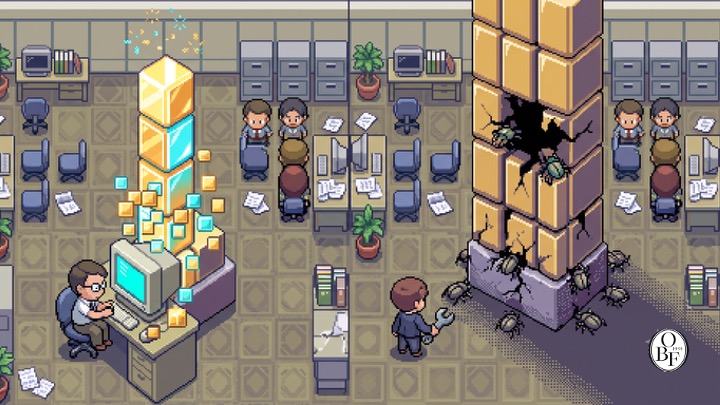 So this looks like a technical problem, but it’s really a problem of measurement and incentives. Throughput shows up immediately on a dashboard, but the cost of degraded maintainability only surfaces as an expense years later. If a manager can only see one of the two, it’s already decided which one gets managed.
In Korea, this distortion goes beyond individual company culture — it’s baked into public-sector contract pricing too. This is the story of the public software maintenance rate3. At the 2017 National Policy Coordination Meeting, the government confirmed a plan to raise the rate from around 15% to 20% by 2022, to close the gap with foreign software (roughly 22%). But according to the Software Policy & Research Institute’s 2019 industry survey, 29.8% of responding companies were still being paid a rate below 10%. The private-sector average was 14.2%, meaning the public sector was actually lower. The practice of fully recognizing the cost of building something new while discounting the cost of fixing it has continued for decades.
Deferred maintenance sometimes surfaces later as an incident. At its March 2026 briefing on digital and IT affairs, the Financial Supervisory Service noted that a substantial share of recent incidents stemmed not from sophisticated hacking techniques but from a failure to follow basic security principles and internal controls. Its diagnosis: incidents arose not from advanced attack methods but from neglecting basic procedures. And following basic procedures is exactly the kind of work that’s hard to get credit for.
The Limits of the Evidence: GitClear, DORA, METR
Reading this far, it’d be easy to conclude “so AI really was the problem.” But that’s premature—we need to look at the limits of this evidence too.
First, GitClear isn’t a neutral observer. It’s a company that sells tools for measuring code quality and developer productivity. A conclusion that quality metrics are deteriorating happens to align with this company’s business interests. A large dataset and a neutral interpretation are two different things.
The DORA survey is also largely self-reported, and what it observes is correlation. This data alone can’t tell us whether teams that use AI heavily become unstable, or whether teams that already move fast and cut corners are simply the ones early to adopt AI.
The most interesting case is the once widely-cited METR study. In its July 2025 release, 16 experienced developers were randomly assigned to 246 real-world tasks4, and the finding was that completion time was 19% longer when using AI. But in February 2026, METR itself revised the experimental design. The reason: there was a selection bias in which developers who benefited more from AI were more reluctant to participate in the “AI-banned” condition. Using only re-participants as the basis, the revised estimate found developers were actually 18% faster. In short, the research team itself walked the finding back toward something closer to “we still don’t know whether AI increases productivity.”
Still, one finding survives this revision: the gap between what developers felt about their speed and what was actually measured. Before starting, participants expected to be 24% faster; after the experiment ended, they still felt they’d been 20% faster. Regardless of which measured value turns out to be correct, the conclusion stands that people cannot accurately gauge changes in their own productivity by feel. And most organizations are, right now, adopting tools and building headcount plans on exactly that kind of feel.
Oswarld’s Lens
I’ve sat in countless product roadmap meetings while building GTM strategy, and one scene repeats almost without exception: stabilization items get pushed down the priority list. What’s interesting is that nobody in the room actually thinks quality doesn’t matter. But when it comes time to pick the sentence that goes into the quarterly goals, “We shipped three new features” beats “We reduced outages by 40%” every time. The first sentence has to prove that something didn’t happen; the second just has to be shown.
Working in data, I’ve also watched management attention gravitate toward whatever is easiest to measure. So I’d argue the root cause here is the organization’s existing incentive structure. If AI cuts the cost of building a feature to 1/10 of what it was, an organization that already favored new features will find it even easier to double down on them. Cleanup and deprecation, by contrast, still demand human judgment and time, so they look comparatively more expensive.
That’s why I think organizations that treat this as a tooling problem will mostly fail. Whether you use Cursor or Claude Code, if there’s no seat at the table for “fixing things” in the quarterly plan, the outcome is the same. DORA’s conclusion says exactly this: success with AI adoption isn’t a tooling problem, it’s a systems problem.
The developer who wrote the original piece didn’t end on pessimism alone — he left room for hope too. While companies pile up maintenance debt, individual developers can now build software on their own that would once have been unthinkable. The same tools that inflate debt inside organizations become, for individuals worn down by that debt, the means to build their own alternative.
Closing
Throughput went up after AI adoption. But in GitClear’s tally, the share of refactoring dropped to 3.8%, and duplicate code blocks rose by 81%. The work of keeping code easy to fix later shrank right alongside it. I think part of the cause is a reward structure where closing a ticket counts as an achievement, while preventing an outage before it happens rarely does. In Korea, that same distortion shows up in the contract pricing itself — in the public-sector software maintenance rate.
This quarter, open up your roadmap and count what percentage is allocated to “fixing and cleaning up.” If it’s close to zero, that’s not a problem with your team — it’s a problem with the plan.
Have you ever seen an organization spend an entire quarter on stabilization instead of new features? I’m especially curious how that decision got approved, and how that team was treated in the next performance review.
💬 I’ll work any examples you share into the next issue. 📨 If you have a colleague struggling to force a quality line item into the roadmap, please share this piece with them.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
Primary sources
- GitClear, “The Maintainability Gap: AI Code Quality in 2026”, 2026. ··· Most of today’s figures come from here. That said, keep in mind this company sells code-quality measurement tools, so read with that in mind.
- Google Cloud, “2025 State of AI-assisted Software Development (DORA Report)”, September 2025. ··· The key point is that throughput and instability rise together. The phrase “AI is an amplifier” also comes from this report.
- Becker, J., Rush, N., Barnes, B. & Rein, D., “Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity”, arXiv:2507.09089, July 2025. ··· This is the original source for the 19% figure. I’d strongly recommend reading it alongside the follow-up piece below.
- METR, “We are Changing our Developer Productivity Experiment Design”, February 2026. ··· A record of the research team acknowledging their own selection bias and revising their design. The act of publicly correcting one’s own research is worth watching in itself.
- Software Policy Institute, “Public-sector software maintenance projects need to close the budget blind spot”. ··· This piece covers the gap between the target maintenance rate and reality. A good starting point for understanding Korea’s structural background.
Background
- DORA, “Balancing AI tensions: Moving from AI adoption to effective SDLC use”, 2026. ··· An analysis showing that time saved on generation by AI gets reallocated to verification. This connects to Chapter 3 of today’s piece.
- Legal Times (Beopryul Sinmun), “Key content and implications of the 2026 briefing on digital/IT financial supervision”, March 2026. ··· This lays out diagnoses of the causes behind incidents in the financial sector. Useful for checking the regulatory perspective.
Past issues worth reading alongside this one

📝 Glossary
Footnotes
-
Delivery instability: How often unplanned redeployments are needed after shipping new code, due to outages or defects. Unlike speed, this is a metric users feel immediately. ↩
-
Refactoring: Reorganizing the structure of code without changing what the program does. It’s less like adding a new room and more like tidying up the belongings you already have. ↩
-
Maintenance rate: A ratio multiplied by software development cost to set the annual maintenance budget. At a 10% rate, a system that cost ₩100,000,000 (~$72,000) to build would have an annual maintenance cost of ₩10,000,000 (~$7,200). ↩
-
Randomized assignment: Randomly sorting participants or tasks into experimental conditions. This reduces the chance that differences outside the conditions themselves get mixed into the results, making it easier to speak of causation than with a simple comparison. ↩
Related issues
Kimi K3: 2.8T Parameters You Can't Run at Home
Kimi K3 tips the scales at over 1.5TB, so even openly released weights demand server-grade memory, not a personal machine.
AI & TechWhat Actually Checks AI's Output Now?
Prompt, context, loop engineering—the labels keep changing, but the real question is what verifies AI's results.
AI & TechWhy We Outsource Judgment Despite Our 20-Watt Brain
AI models can be copied and run anywhere, but that convenience is quietly training us to skip the step of checking the results.
AI & Tech
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?