

Why Chinese Firms Are Racing to Install OpenClaw
From install lines to messenger hookups, here's what my Chinese clients are telling me about OpenClaw's sudden rise.
SocietyOpenClaw Users Lined Up Outside Tencent’s Headquarters
On March 6, 2026, a line formed outside Tencent’s headquarters in Shenzhen, China, of people waiting to get OpenClaw installed. According to Yicai (China Business News), close to a thousand people showed up — developers and AI enthusiasts alike. It was an event where Tencent Cloud engineers helped attendees install and configure the software.
OpenClaw is an open-source AI agent that uses a crayfish as its icon. In China, the process of installing and configuring it has picked up a nickname: “yǎng xiā” (养虾, “raising crayfish”). Model companies and cloud providers are now scrambling to capture this demand.
I have a personal reason for paying attention to this trend. My GTM consulting firm, INLEVEL9, counts ByteDance and MiniMax among its Chinese clients. Through conversations with these companies, I’ve come to feel that the level of local interest far exceeds what’s understood back home. In this piece, I’ll walk through publicly available material alongside what I’ve picked up from those exchanges.
What Kind of Tool Is OpenClaw
It’s a project developer Peter Steinberger started in November 2025. It was first known as Clawdbot, then became Moltbot after Anthropic requested a name change, before finally settling on OpenClaw. The developer announced the new name on January 29, 2026.
You install OpenClaw on a laptop or a dedicated server and direct it through a messaging app. The AI model you connect it to decides what to do, then uses whatever tools you’ve permitted to read files or execute code. Email and browser access can also be enabled depending on how you configure connections and permissions.
Keep the server running and it can execute scheduled tasks, but simply installing it doesn’t give you an employee who handles everything on its own. You still have to decide which model to use, what it’s allowed to access, and how you’ll check its output. And even if you install OpenClaw on your own personal computer, connecting it to an external model API means your requests get sent to that provider.
More Model Calls Mean the Costs Pile Up Too
An agent may call the model multiple times just to finish a single job. Searching for material, comparing what it’s read, drafting, then revising — each of these steps generates its own input and output. A token, in this context, is simply the unit of text the model processes.
How much gets consumed varies enormously depending on the task and the setup. Even for the same research job, the bill can differ based on how long the documents are, how many iterations run, and whether prior context gets resent each time. It’s hard to treat one user’s giant invoice as representative of the average monthly cost across all users.
Still, the usage figures companies have disclosed show a clear upward trend. At an earnings call on March 2nd, MiniMax executives said daily average token consumption for the M2 series in February 2026 was more than 6 times what it had been in December 2025. They also noted that February ARR had passed $150 million. ARR is a revenue metric annualized from a run rate — it should be kept distinct from revenue actually earned over a full year.
This figure spans multiple products and use cases, so it doesn’t mean the entire increase came from OpenClaw. Still, it illustrates just how quickly usage of models built for agentic and coding work can scale.
Cloud providers, for their part, are rolling out services to make installation easier. Yicai, a Chinese financial-news outlet, reported the company’s claim that Tencent Lighthouse’s OpenClaw user base had surpassed 100,000. Tencent and Baidu, among others, introduced one-click deployment features, and Feishu hosted a livestream showcasing use cases.
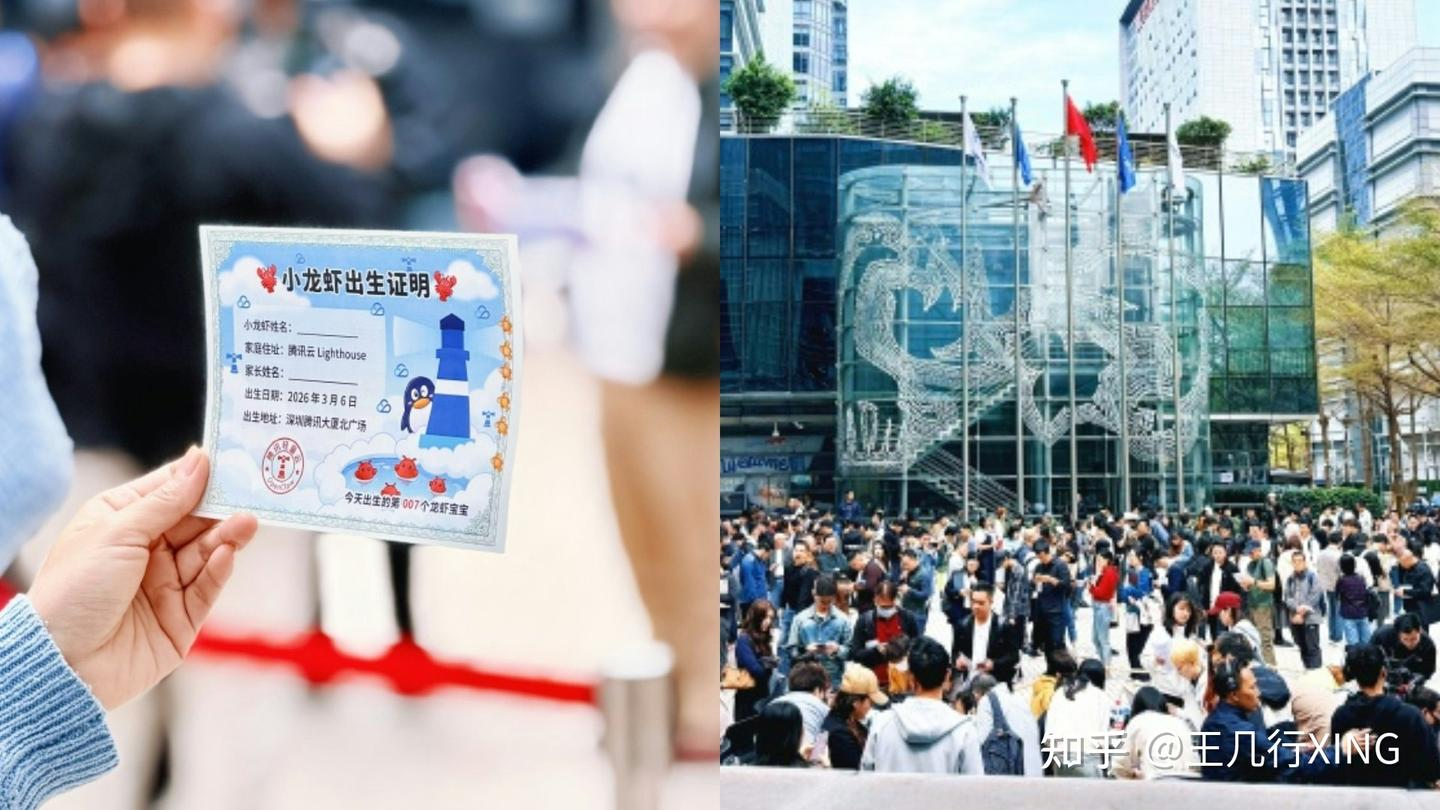
A photo from an OpenClaw installation event. On the left, a “crayfish birth certificate” bearing the Tencent Lighthouse logo is visible.
Users need to check server rental fees and model-call charges separately. Free installation support doesn’t necessarily mean usage afterward is free too. Even flat-rate coding subscriptions come with call limits and usage conditions worth scrutinizing. A product name alone can’t tell you the final cost of getting one job done.
For vendors, this creates an opportunity to grow server and model usage. For users, though, it makes the total cost of completing a single task — rather than the price of any one response — the number that actually matters. And spending a lot of tokens is no proof, by itself, that a lot of useful work got done.
Messengers Become the Gateway to Agents
In China, people chat, pay, and use countless services through WeChat. If you’ve visited China or kept in touch with Chinese friends, you’ve probably felt just how far WeChat’s reach extends.
OpenClaw isn’t confined to its own standalone screen, either. You can send it commands directly from whichever messenger you’ve connected—WhatsApp, Telegram, Slack, Discord. Since China restricts access to many foreign services, connecting to the messengers people actually use there becomes essential.
Tencent Lighthouse now lets users connect through QQ and the enterprise messenger WeCom. Feishu (ByteDance’s workplace messaging app) drew user attention by showcasing how to use OpenClaw, too. It’s all part of a broader push to let people summon an agent right inside the chat windows they already use.
I think this creates a new competitive challenge for messenger companies. What matters now goes beyond simple connectivity—whether files and schedules can be exchanged properly, whether permissions can be managed, whether errors that occur mid-task can be checked. It’s still too early to say this shift alone has changed WeChat’s standing.
Being open source makes it easier for companies to connect their own services. That doesn’t mean every platform has to allow integration, though. Account protection, access permissions, and operating policy are each company’s own call.
Cumulative cost matters more when choosing a model
The rise in usage of Chinese models is worth watching alongside this trend. MiniMax executives explained that M2.5 climbed to the top of OpenRouter’s rankings after launch. OpenRouter is a platform that provides API access to multiple models, and usage on it can’t be equated with global AI market share.
Price differences are a factor worth weighing when choosing a model. Here’s what the official general API pricing looked like at launch. Figures are per 1 million tokens each for input and output, excluding caching or other discounts.
| Model | Input | Output |
|---|---|---|
| MiniMax M2.5 (standard) | $0.15 | $1.20 |
| MiniMax M2.5 Lightning | $0.30 | $2.40 |
| Claude Opus 4.6 | $5 | $25 |
MiniMax presented the standard and Lightning versions as products with identical performance but different processing speeds. Opus 4.6 also had a separate rate that applied to long inputs at the time. Before comparing, you need to make sure you’re comparing the same type of request under the same rate conditions.
Performance also needs to be checked task by task. MiniMax reported M2.5’s SWE-bench Verified score as 80.2%, a figure measuring code-fix tasks. Even within the same announcement, the score shifted when the execution tool was swapped for Droid or OpenCode. It’s hard to read a difference on a single benchmark as a performance difference across every task.
Even if the per-call rate is low, if it takes more retries or long human correction afterward, the actual savings shrink. Conversely, if a model reliably delivers the needed quality, there’s a reason to use the cheaper model for repetitive work. I think the more sensible comparison is how much it cost per task that actually passed the bar.
The trend of using Chinese models was also covered in an earlier piece, Silicon Valley Is ‘Quietly’ Using Chinese AI. It’s a topic that calls for looking at a model’s openness, pricing, and execution environment together. There are too many intertwined factors to explain price competitiveness or business strategy through GPU export restrictions alone.
Oswarld’s Lens
At first, I figured this was just another “AI agent” hype cycle. But the more I dug into the material, the more it looked like an actual case study of where this gets used and where the costs show up. Beyond what the technology can do, I thought we needed to look at who pays for it and through what channel people actually end up using it.
What I’m watching is sustained usage. I want to know what tasks people keep handing off after installation, how much they get charged each time they do, and whether they can trust the results. Cloud providers and model companies only turn this into revenue if the experience keeps people coming back—that’s the real opportunity to lock in users.
Security concerns have already surfaced in practice. In guidance published in March, China’s National Computer Network Emergency Response Technical Team/Coordination Center (CNCERT) warned about malicious plugins, agents being fooled by instructions embedded in external documents, mistaken deletion operations, and information leaks through vulnerabilities. We need to watch whether control over permissions and execution outcomes can keep pace with the speed at which features are being added.
What this current wave shows us is genuine interest in installing and trying these tools directly, plus companies moving to support that behavior. The long-term market size and actual productivity gains still need to be watched. In Korea too, it’s worth tracking how this connects to messengers like KakaoTalk, how cloud costs get managed, and which models actually deliver the quality needed.
How I Track China’s Changes
I try to visit Shanghai and Shenzhen in person, or dig through trending posts on Bilibili, Douyin, and Weibo. These are where you can catch, respectively, long-form video, short-form video, and social media reactions. I use a translator, of course. Change moves fast there, and I’ve noticed there’s always a lag before it reaches Korea. It’s become clear to me that I need to watch China’s moves alongside America’s.
If you’re preparing coverage or interviews on ByteDance and MiniMax, feel free to reach out. I can help make connections through relationships I’ve built in my consulting work.
I plan to cover more of this kind of on-the-ground reporting in the membership tier going forward. As of this issue’s publication, membership costs ₩3,000 (~$2.2) per month, and it gives you unlimited access to posts older than 30 days. Free subscribers can still read the latest posts without any restrictions.
Keep the perspective, not the noise.
We choose one consequential shift and trace what sits beneath it, every other day.
Confirm once to finish subscribing.
Already a subscriber? Sign in to join the conversation


References & Further Reading
- Peter Steinberger, Introducing OpenClaw, January 29, 2026. The developer’s own account of the project’s origins, its name change, and how it runs.
- Yicai, OpenClaw installation event outside Tencent’s headquarters and use cases, March 6, 2026. On-the-ground reporting along with Tencent’s own account of user numbers.
- MiniMax, 2025 earnings call transcript, March 2, 2026. Confirms usage figures and ARR as described by management.
- MiniMax, February 13, 2026 version of the M2.5 launch materials. Source for the standard and Lightning pricing tiers and benchmark results.
- Anthropic, Introducing Claude Opus 4.6, February 5, 2026. Explains API pricing and evaluation conditions at launch.
- CNCERT, Safety advisory on OpenClaw usage risks, March 2026. Covers permission scope, plugin risks, and data-leakage concerns.
- Poe Zhao, OpenClaw Conquered China in 100 Days, March 9, 2026. A useful reference for thinking through why Chinese companies adopted the tool.
Related issues
How Yakult Delivery Workers Check on Their Neighbors
Japan's Yakult Ladies and Korea's hy delivery workers quietly track elderly customers' well-being during routine drop-offs.
SocietyClaude's Military Use: Do Principles Hold in Contracts?
I trace Anthropic's clash with Washington through statements and contracts, separating military AI use from human control.
SocietyWhat Huxley's 1961 Interview Taught Me About Algorithms
Huxley's 1961 BBC interview and Island made me question what recommendation algorithms actually optimize for.
Society
Your take shapes the next issue
What resonated most in this issue, or where has your experience been different?